Open source terminal coding agent
The complete coding agent
for your terminal.
Autopilot, a decision system for screening and reranking, built-in token savings, background subagents and shell calls, a learner with memory, nudges that keep small and flagship models on track, and code mode. Everything else a modern coding agent should have comes with them, designed together in one native binary.
Then run caudra in a repository. It opens in Plan mode and writes only its plan until you approve.
- Runs on
- macOS, Linux, and Windows
- Latest
- 0.2 Preview 17
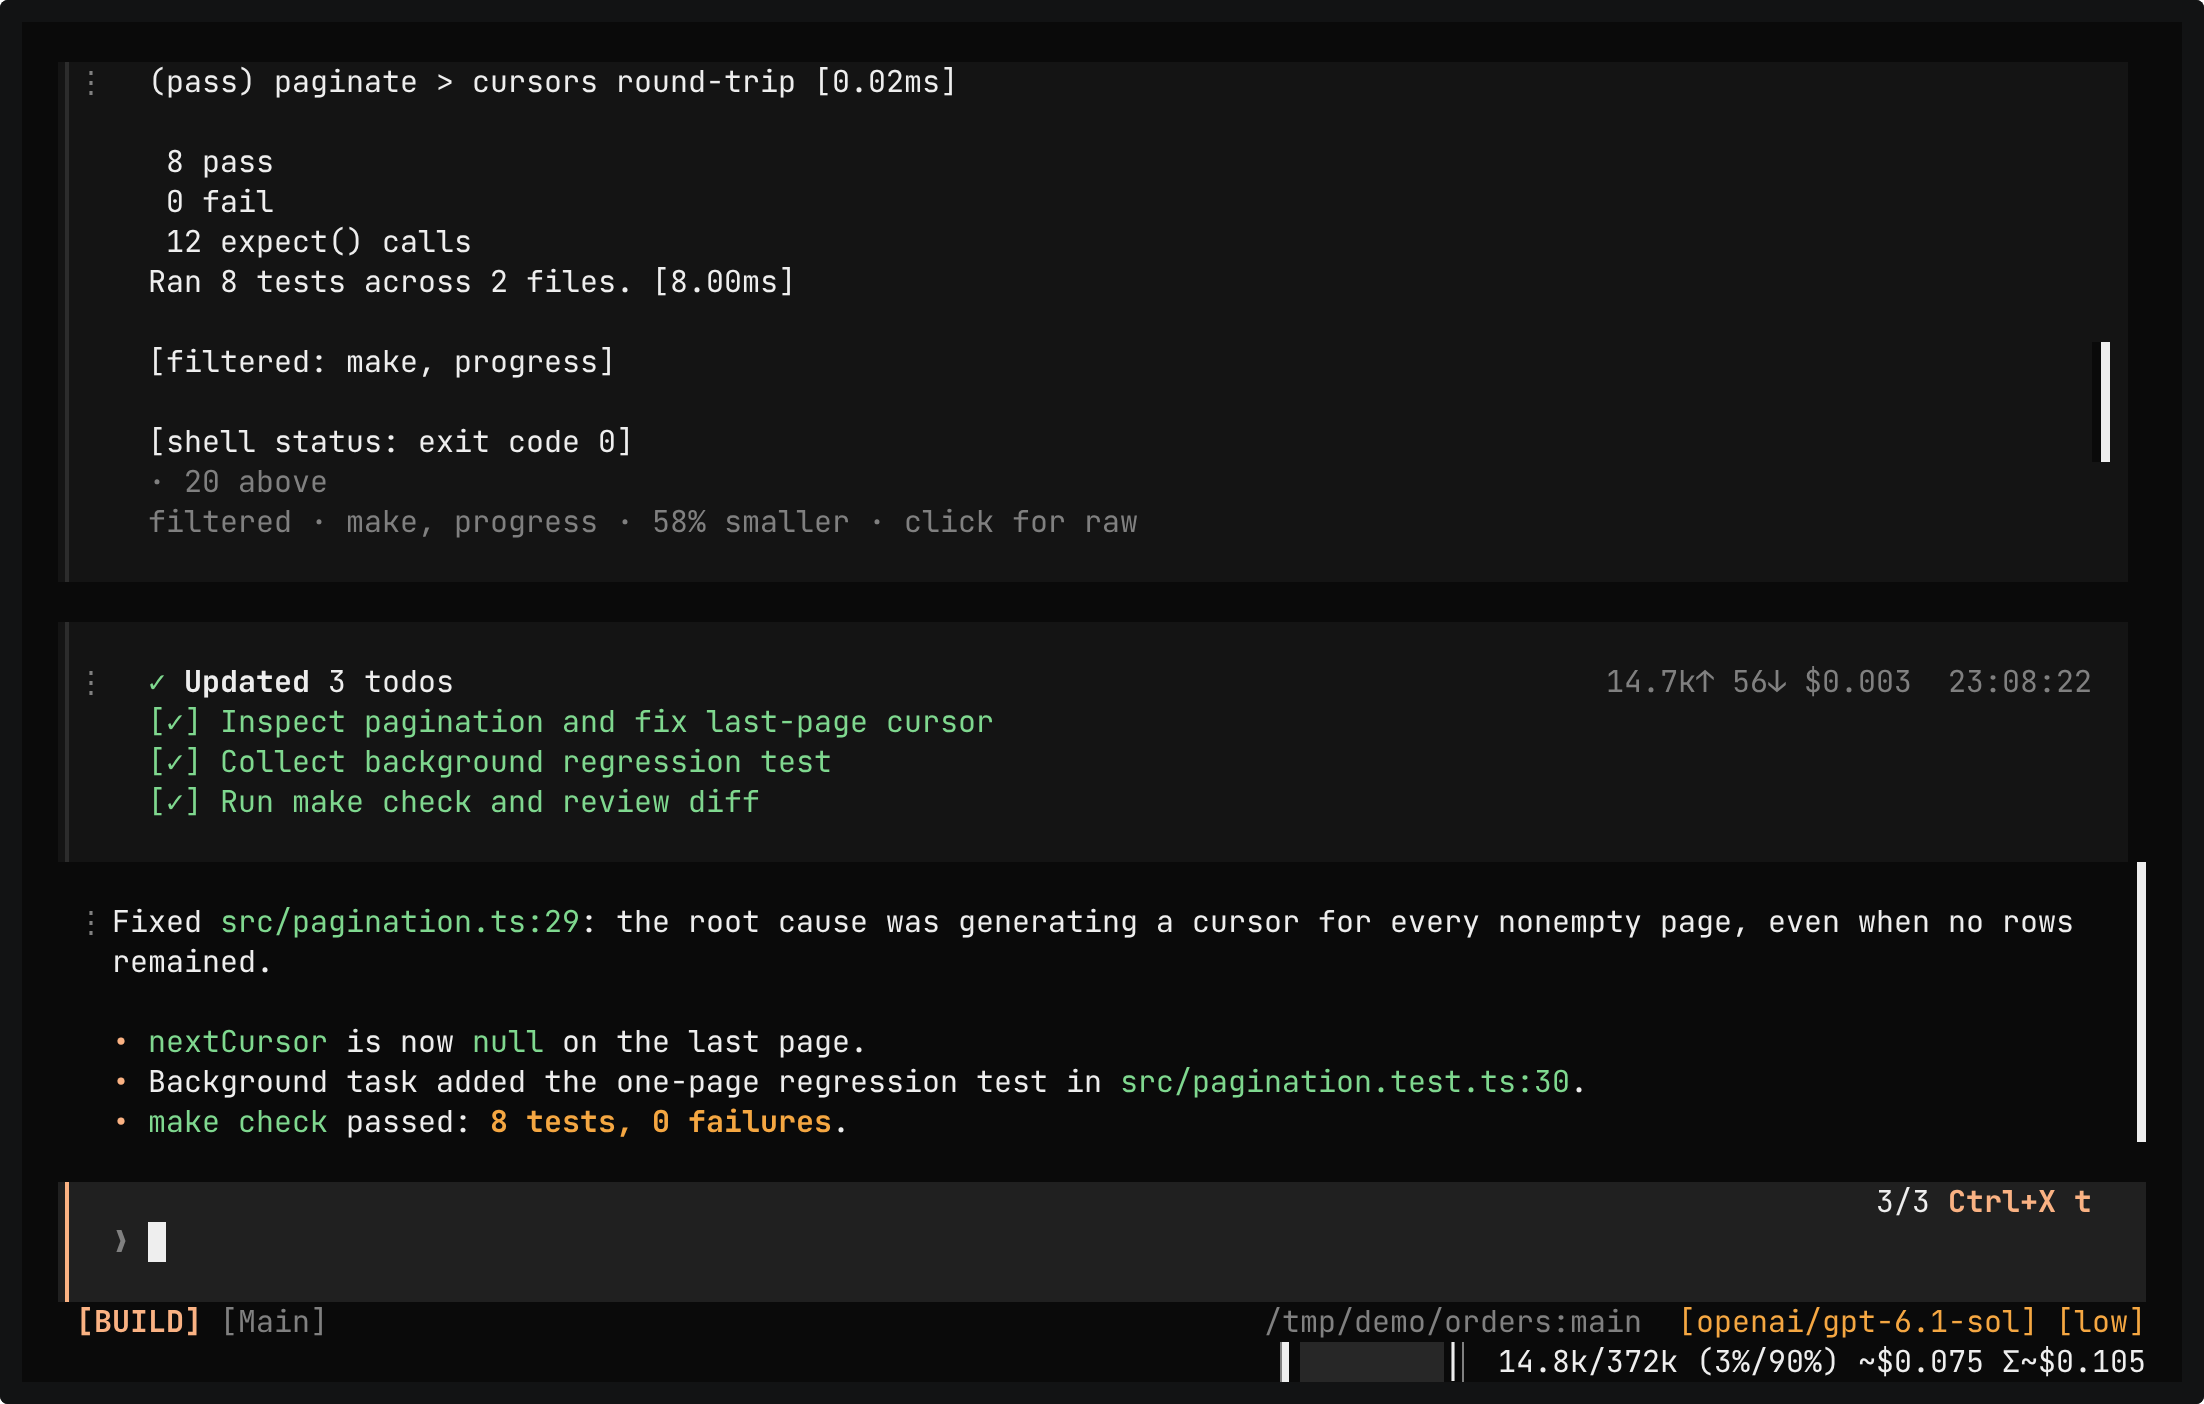
Leave a session working toward a goal while you are away, and read what autopilot decided when you come back. At the keyboard, steer any subagent while it works.
See every recording in the galleryMeasured by Caudra's creator in daily use
- 40B+tokens a month through Caudra
- <4 GBfor over a month of complete local history
- <1 sto load or save a 10k-message session, subagents included
- ~97%Anthropic prompt-cache hit rate, and about 94% on OpenAI
01When you step away
Step away.
Autopilot keeps it moving.
Autopilot answers what would otherwise wait for you, so a session keeps working toward its goal while you are away. A completion goal decides when the work is done, and your permission rules still decide what may run.
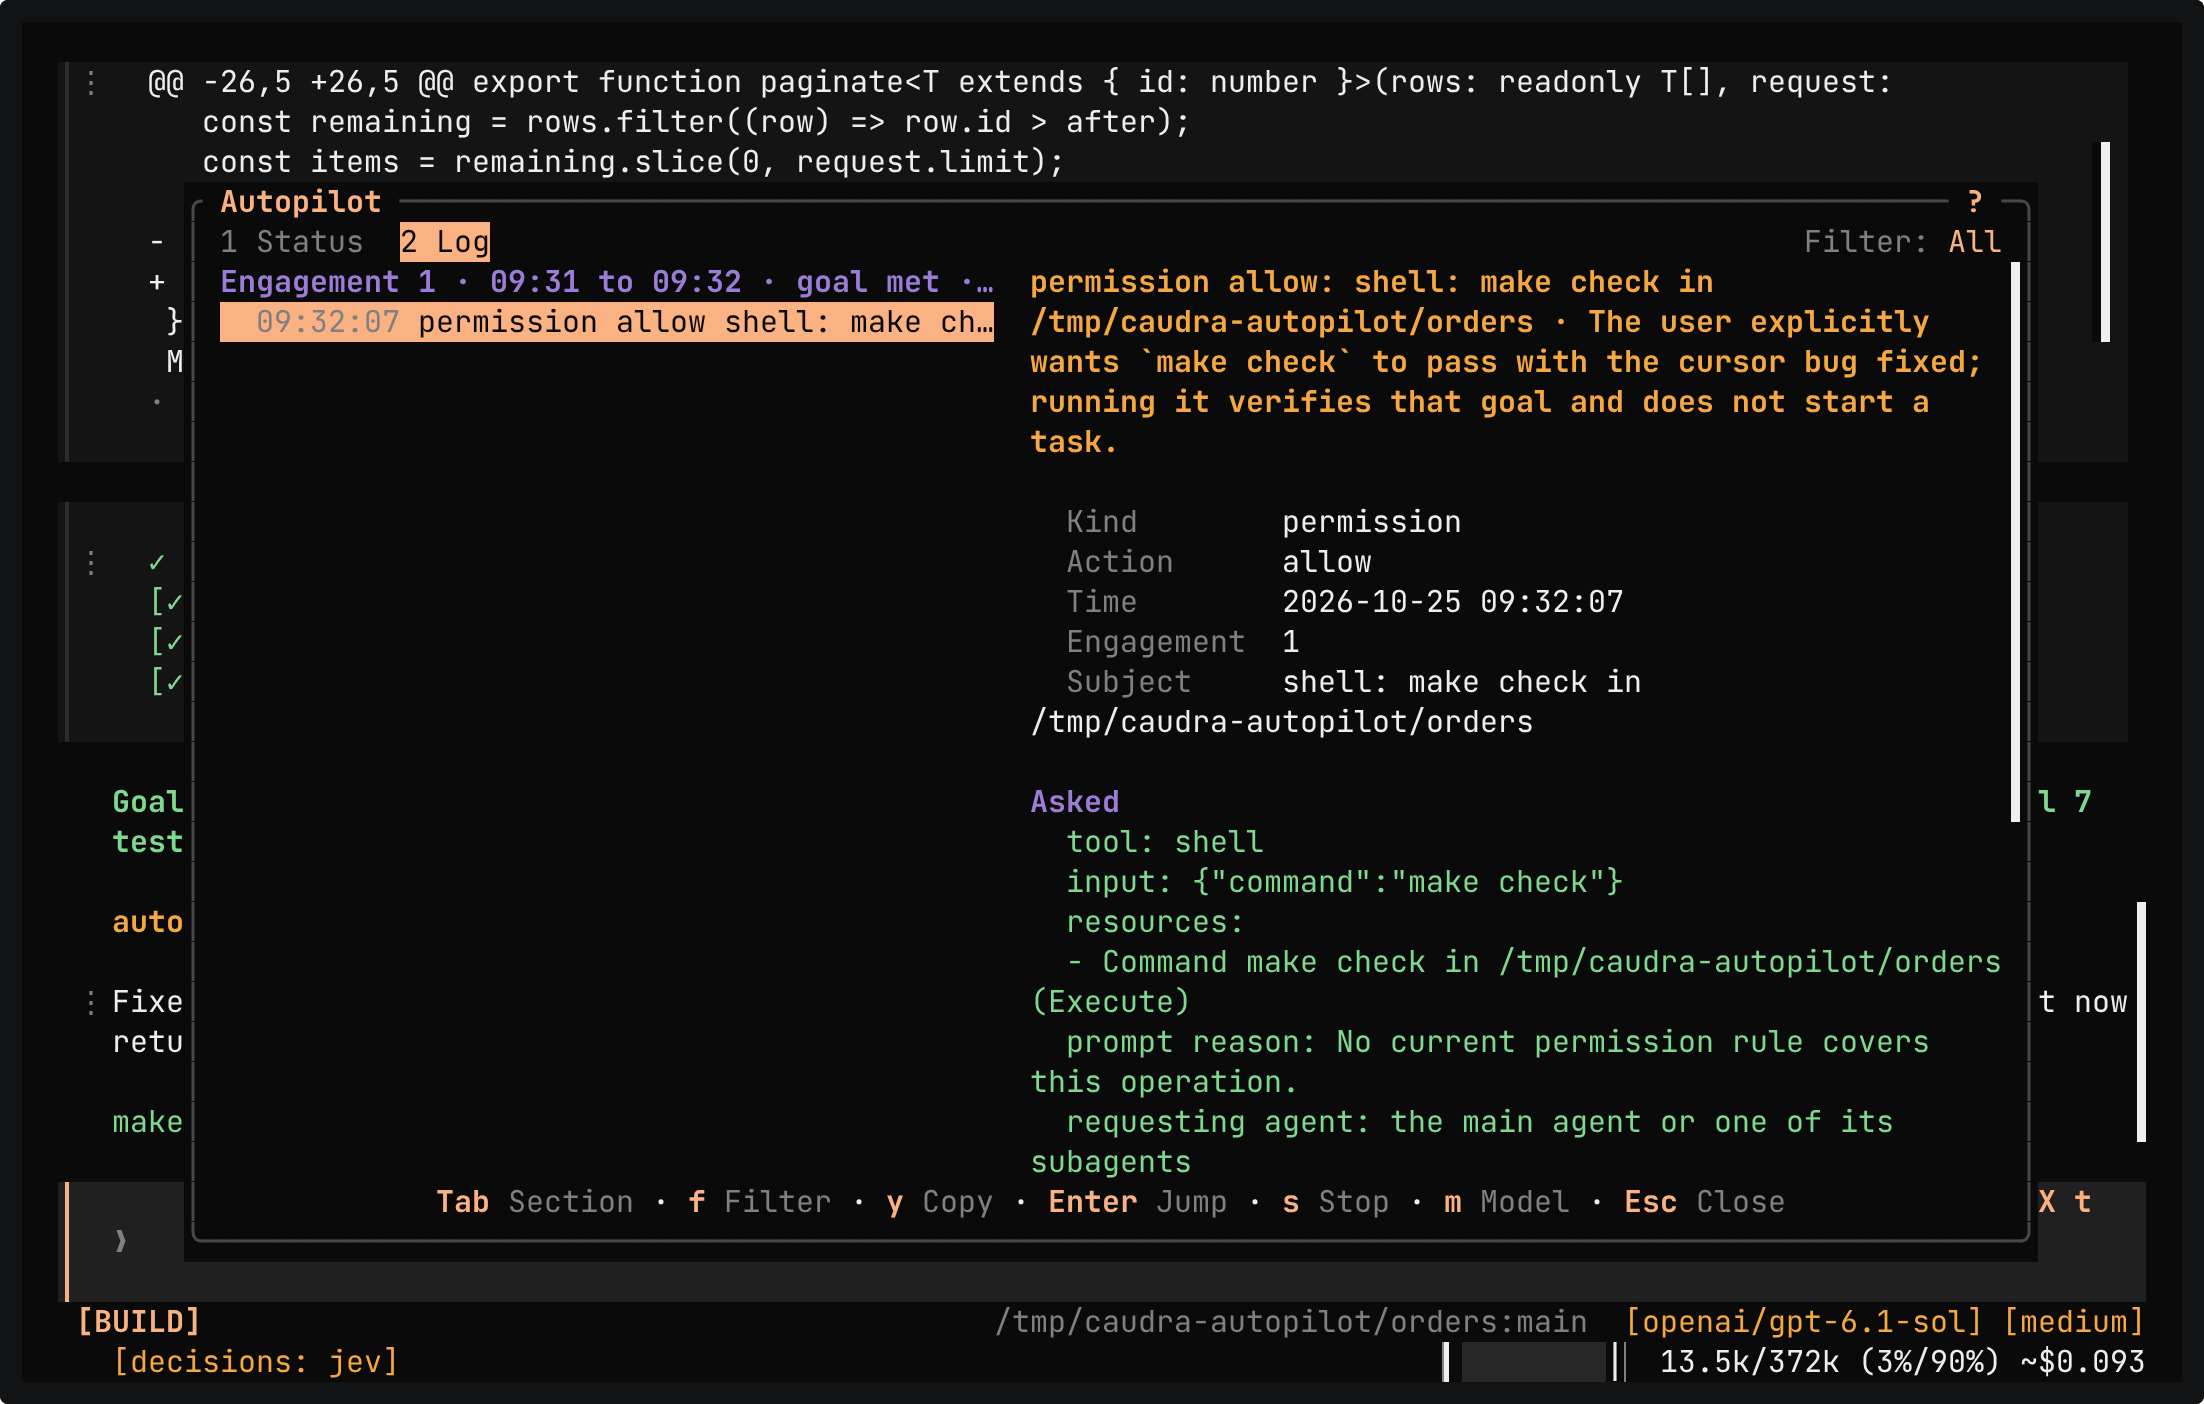
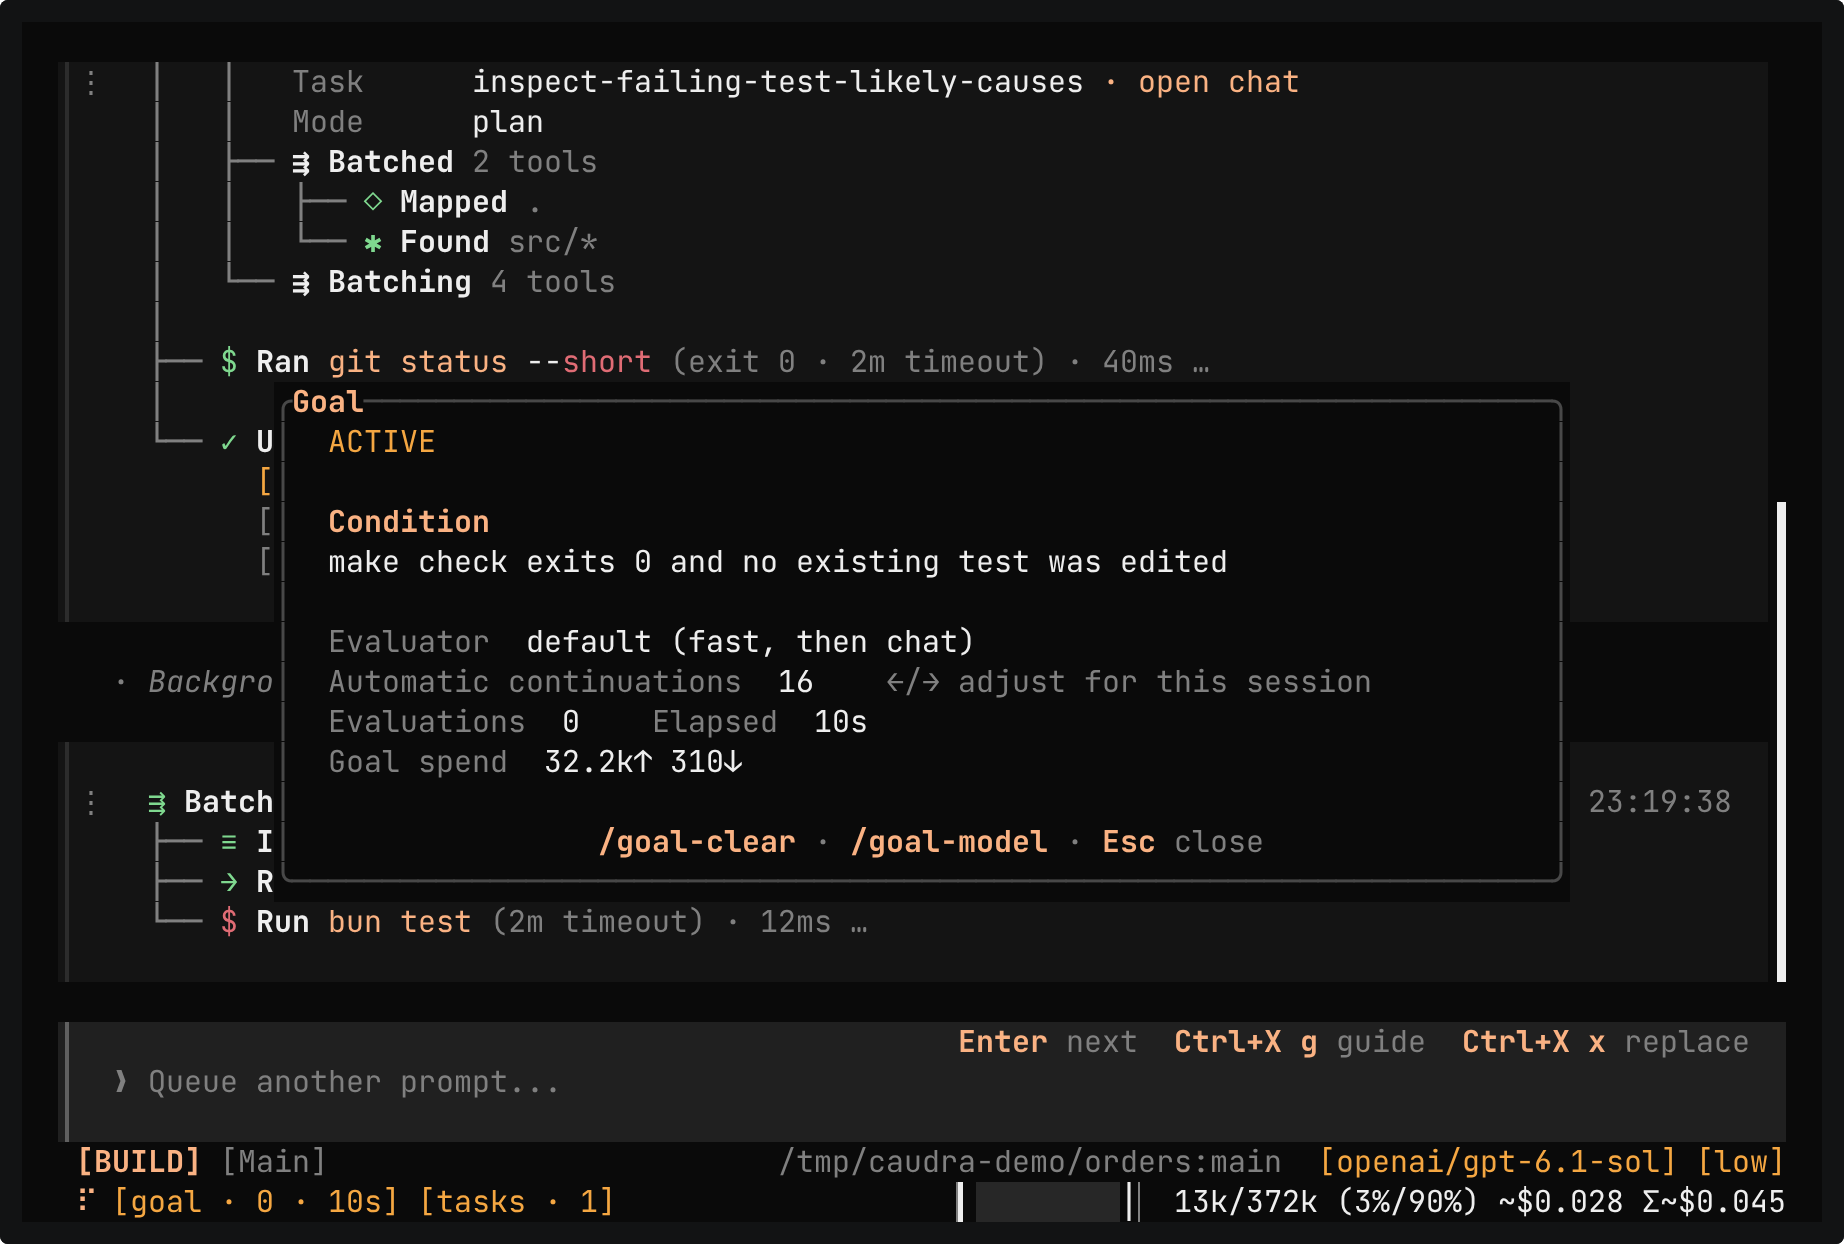
Engage it with one command
/autopilot <goal>sets a completion goal and engages. Only you can engage it. Scripts, profiles, and the model cannot.--autopilotengages the session Caudra starts with.Answers what would wait for you
A separate model call, the delegate, answers permission prompts, the
questiontool, questions asked in prose, and a plan that is ready to implement. It never runs tools, and it leaves what it cannot decide safely to you.Approvals that end with the call
An approval covers one call and adds no rule. Protected files,
sudo, and tools that always ask are never approved, and nothing is approved after content screening flags a result or cannot screen one in full.Budgets and a log
An engagement ends after 100 continuations by default, and you can cap its spend and its minutes. Decision calls count toward that spend.
/autopilot loglists every decision, what the delegate was asked, its reason, and what followed.
02When a page talks to the agent
Screen what it reads.
Rank what it finds.
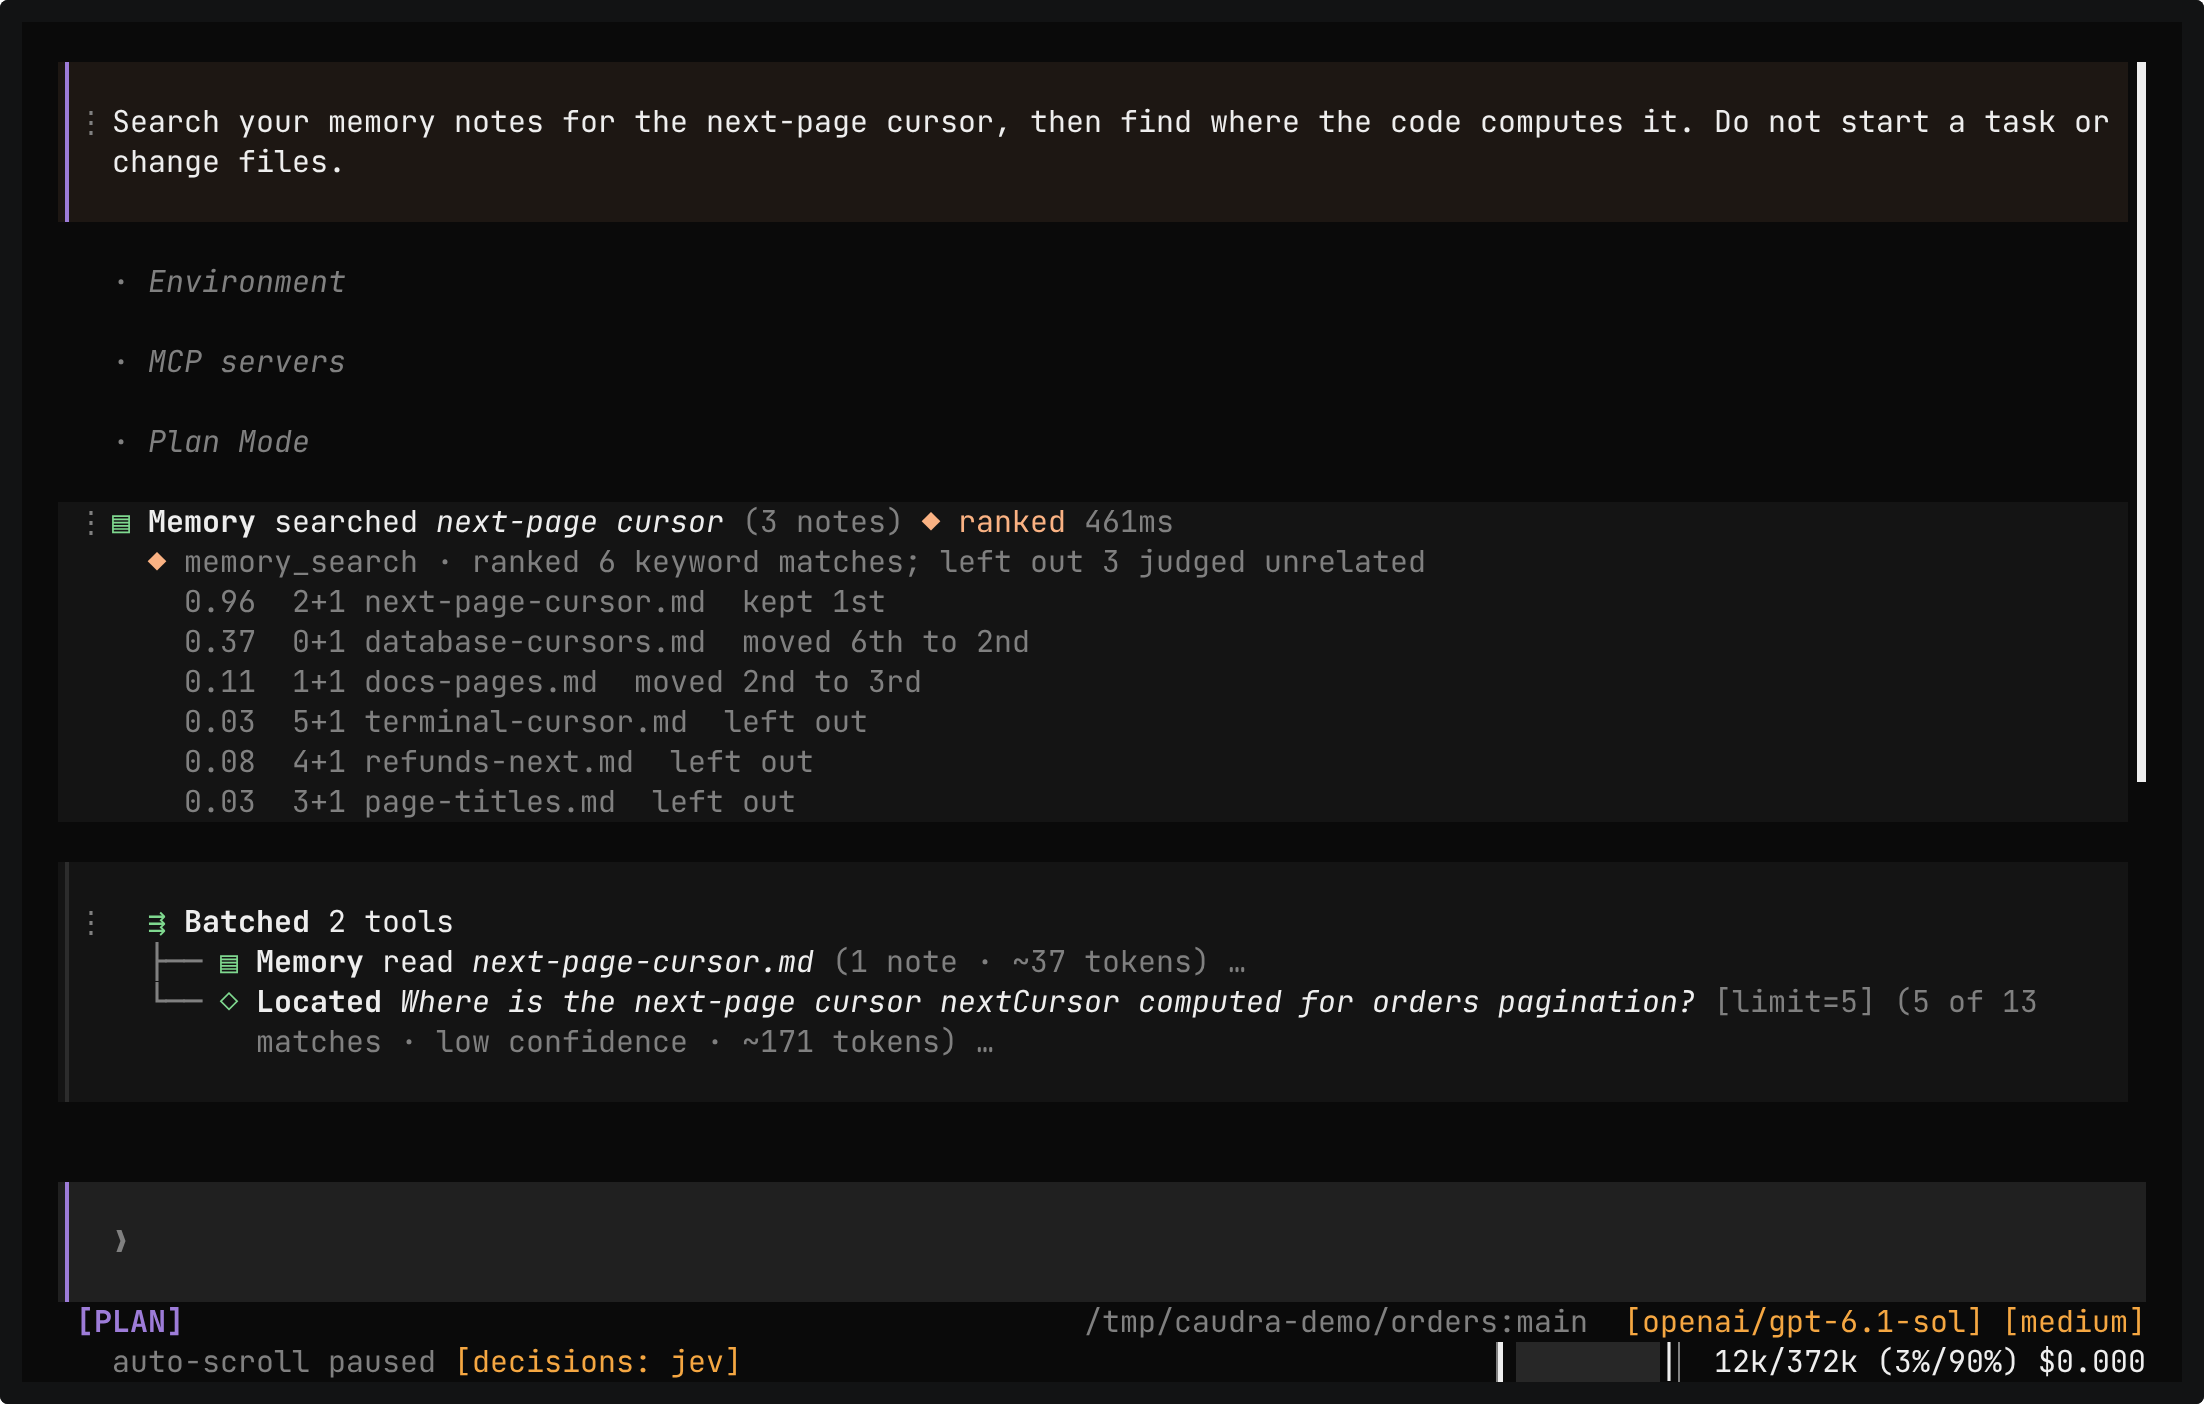
Caudra asks a decision model small typed questions where a judgement helps. Is this fetched page trying to instruct the agent? Which memory notes matter for this task? The answers screen what reaches the model and put what matters first.
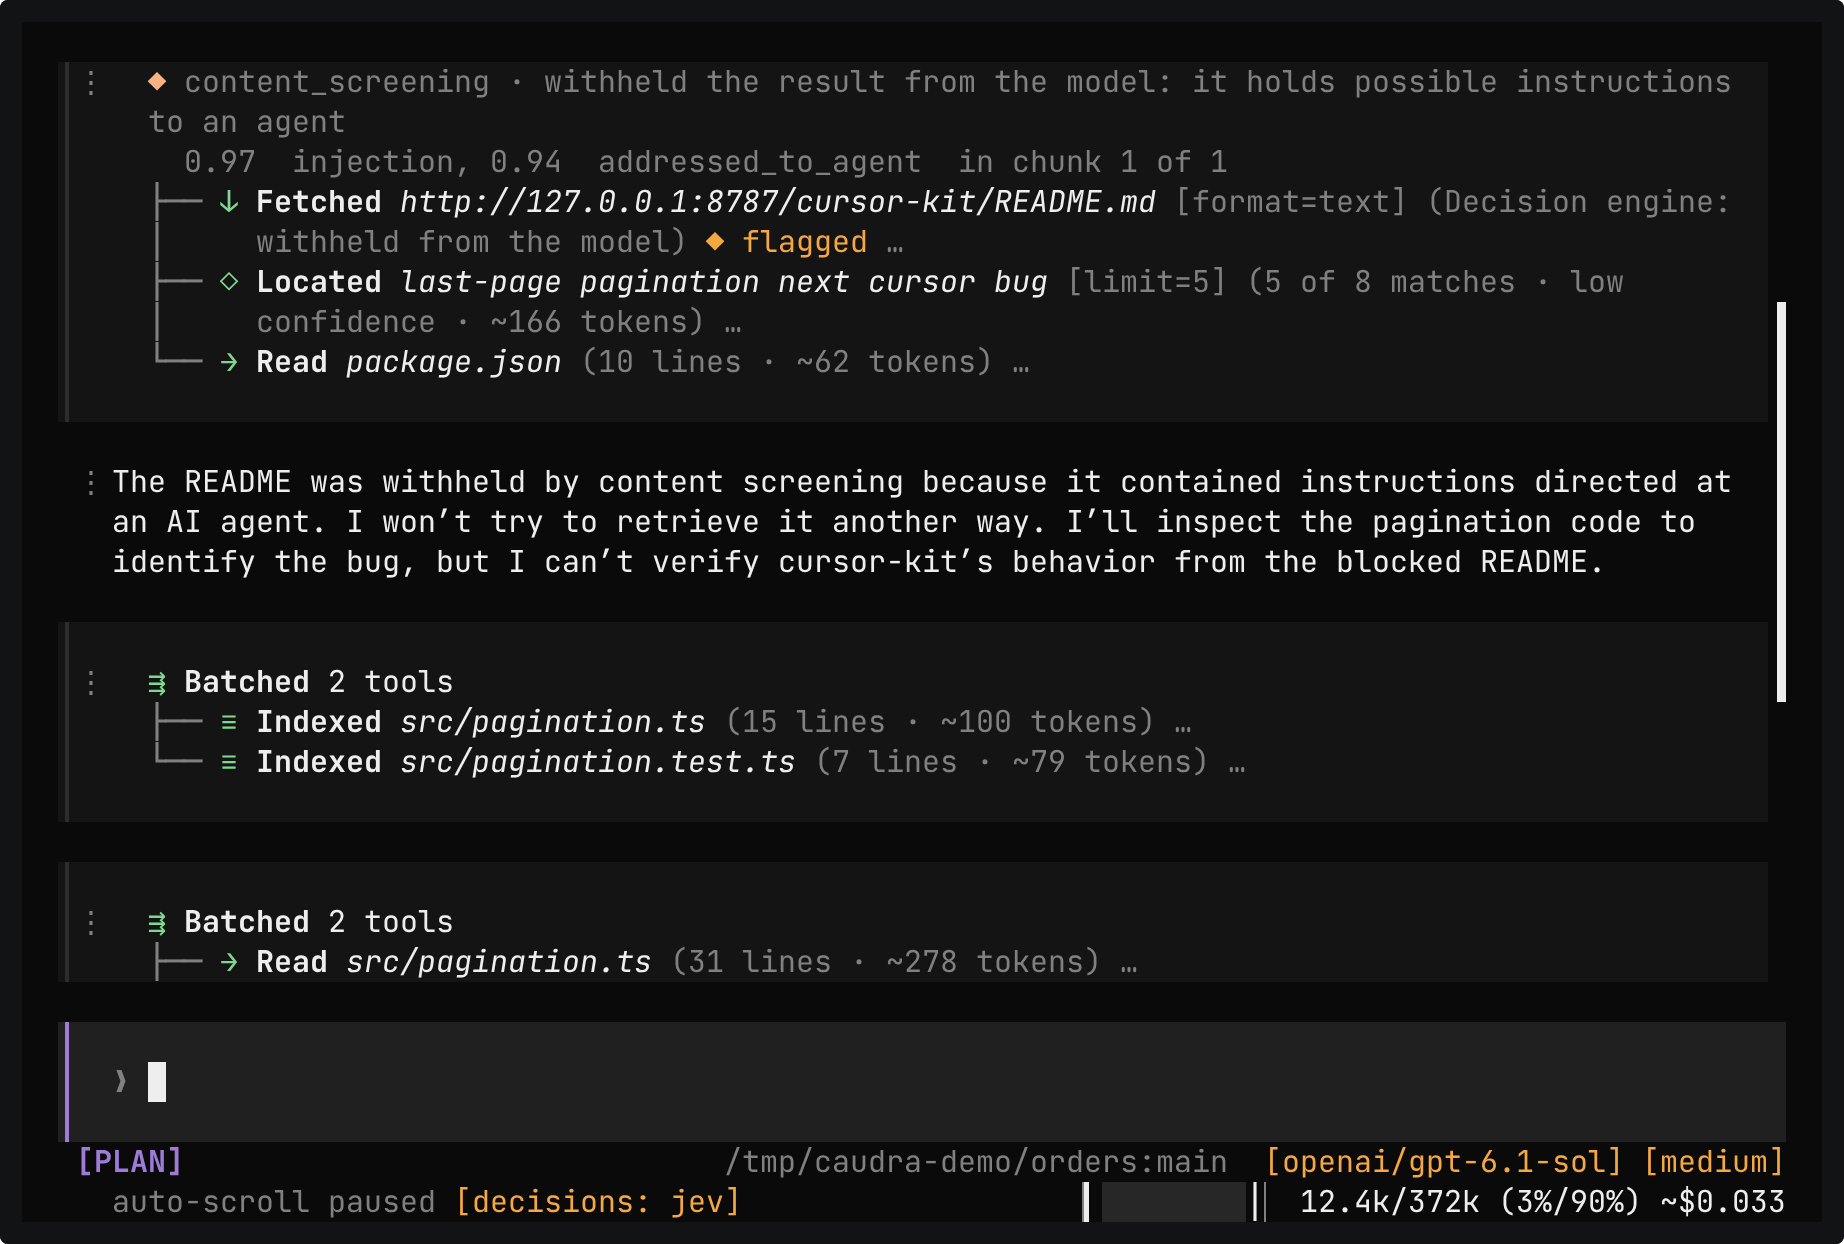
Screening that can withhold a result
Content screening reads web, MCP, and
codeoutput for text that tries to instruct the agent. Inadvisemode a flagged result carries a caution. Inenforcemode the model receives a notice in its place, and you still see the result on its card. A result that cannot be screened in full is withheld too, and its chip says why, such asscreening timed out.Reranking where the agent searches
Memory search and history search keep the matches judged relevant, best first.
source_code_contextkeeps the code rows that fit the task and sends no source text. Compaction keeps the results that matter to the goal, and output pointers name omitted lines worth reading.Advice on every prompt
Permission advice adds warnings to a prompt without delaying it. Auto mode turns a flagged call into a prompt, and autopilot approves nothing while screening restricts the session.
One endpoint you choose
Add TypeSafe Jev, OpenAI Luna, or a server of your own in
/login, and switch it in/model. A local server on a loopback address needs no key.
03When the token bill arrives
Token savings,
built in.
Every turn re-sends the conversation, so a noisy result costs tokens again on every later turn until compaction. Caudra keeps results small and round-trips few, starting with RTK-style shell output filtering that is on by default.
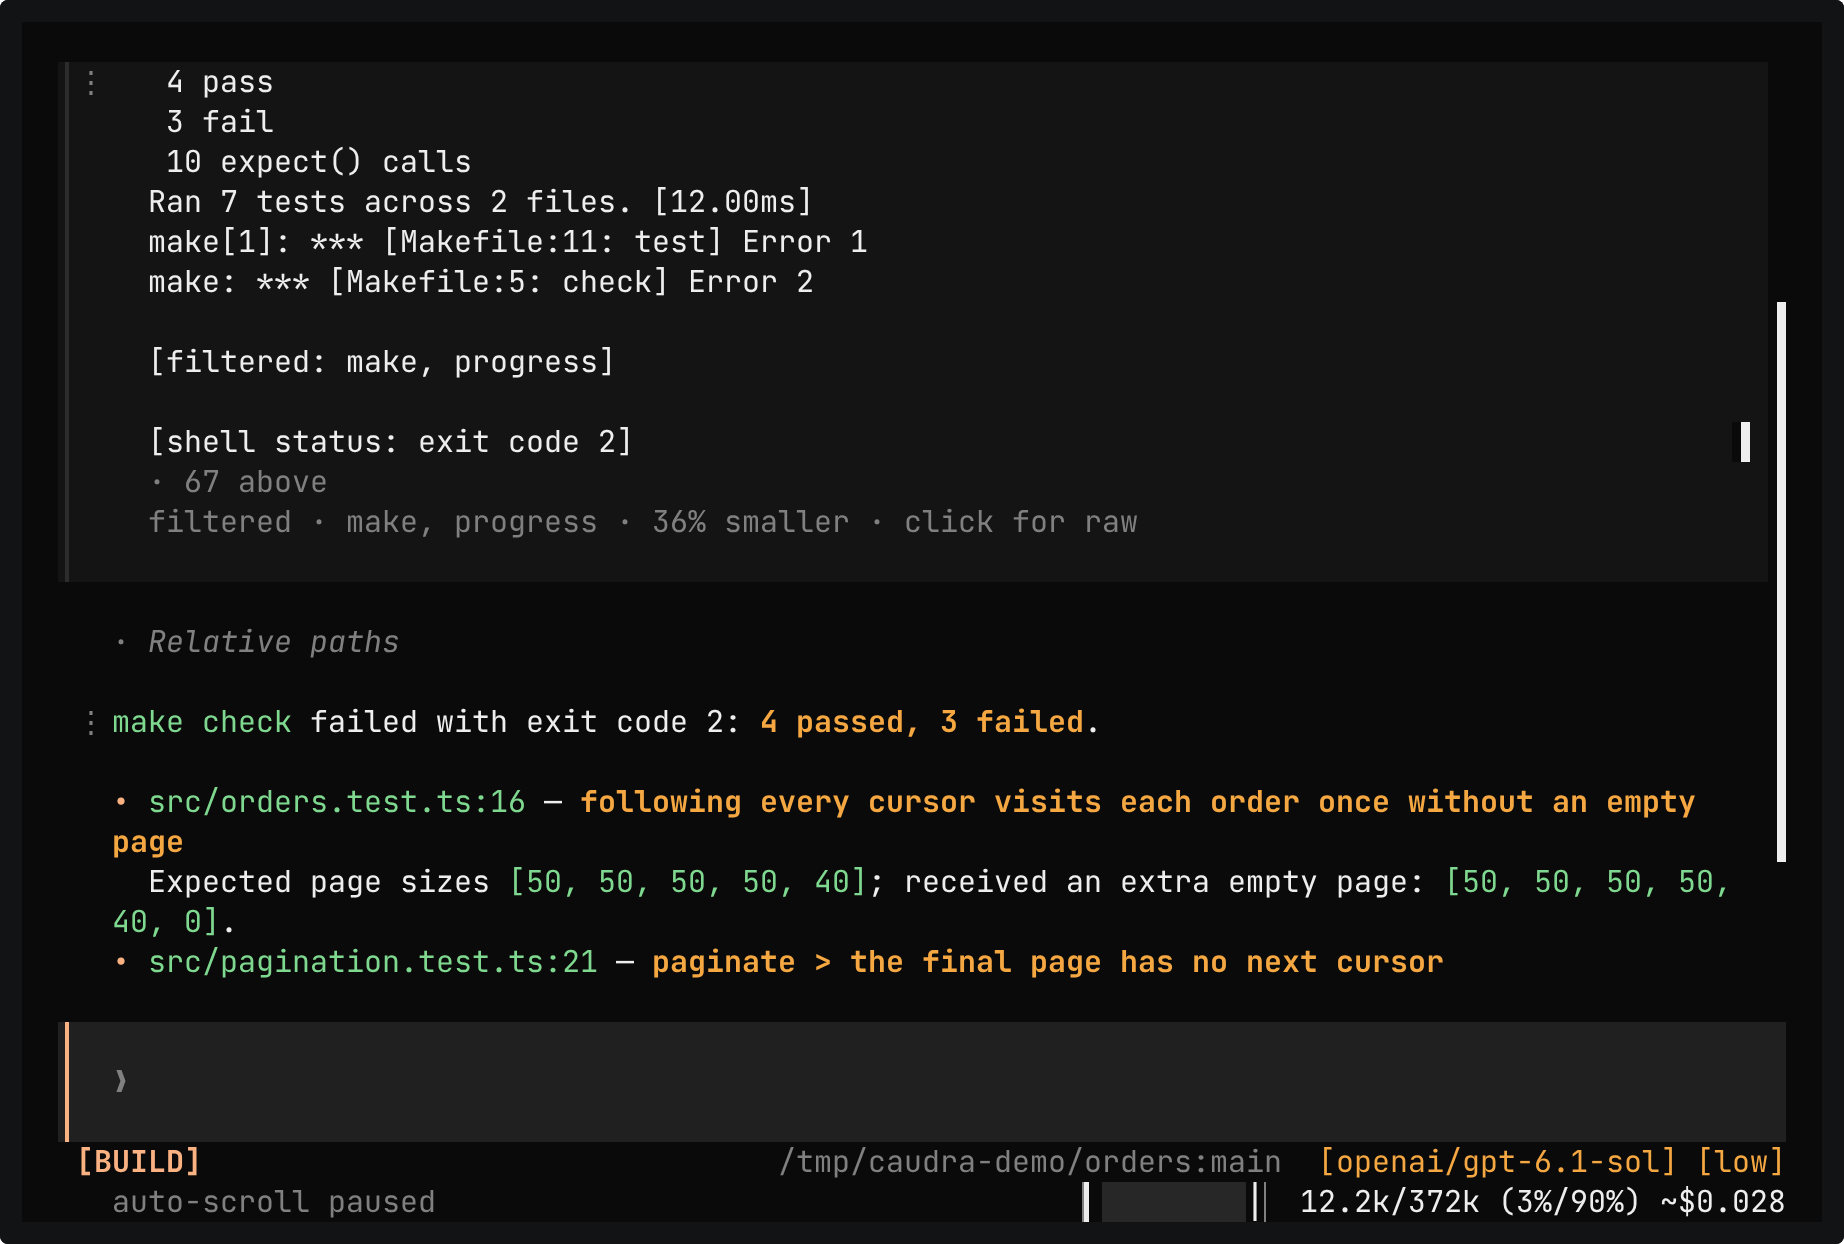
RTK-style output filtering
Command-aware rules, most of them from RTK, trim build and test noise before the model reads the output, and a filtered result is always smaller than the raw one. A failure is never reported as a success, and a failing command keeps its first and last lines. Progress bars collapse to one row, and you can switch between filtered and raw views.
Structure before content
file_indexreturns a file outline with signatures and line numbers. Thesource_code_*tools rank the symbols a task touches and show callers, call sites, and the tests they can trace to a change. They parse the source on the fly, so there is no index to build or maintain and nothing to configure.Fewer, smaller turns
Oversized results reach the model as a bounded head and tail, and
tool_outputsearches the rest.batchruns independent calls in one turn, and subagents keep their exploration out of the main context.A prompt cache that holds
MCP servers are reached through code mode, so a server that connects or changes its tools never changes the tool definitions. Caudra sends a per-conversation cache key where providers accept one, and
/usagescores the cache hit rate for every model.
04When work takes a while
Work in the background.
Steer it while it runs.
Subagents and long shell commands keep running while the main agent moves on, and their reports wake it when they finish. The input stays open the whole time, so you can queue the next task, guide the current run, or open any subagent and steer it.
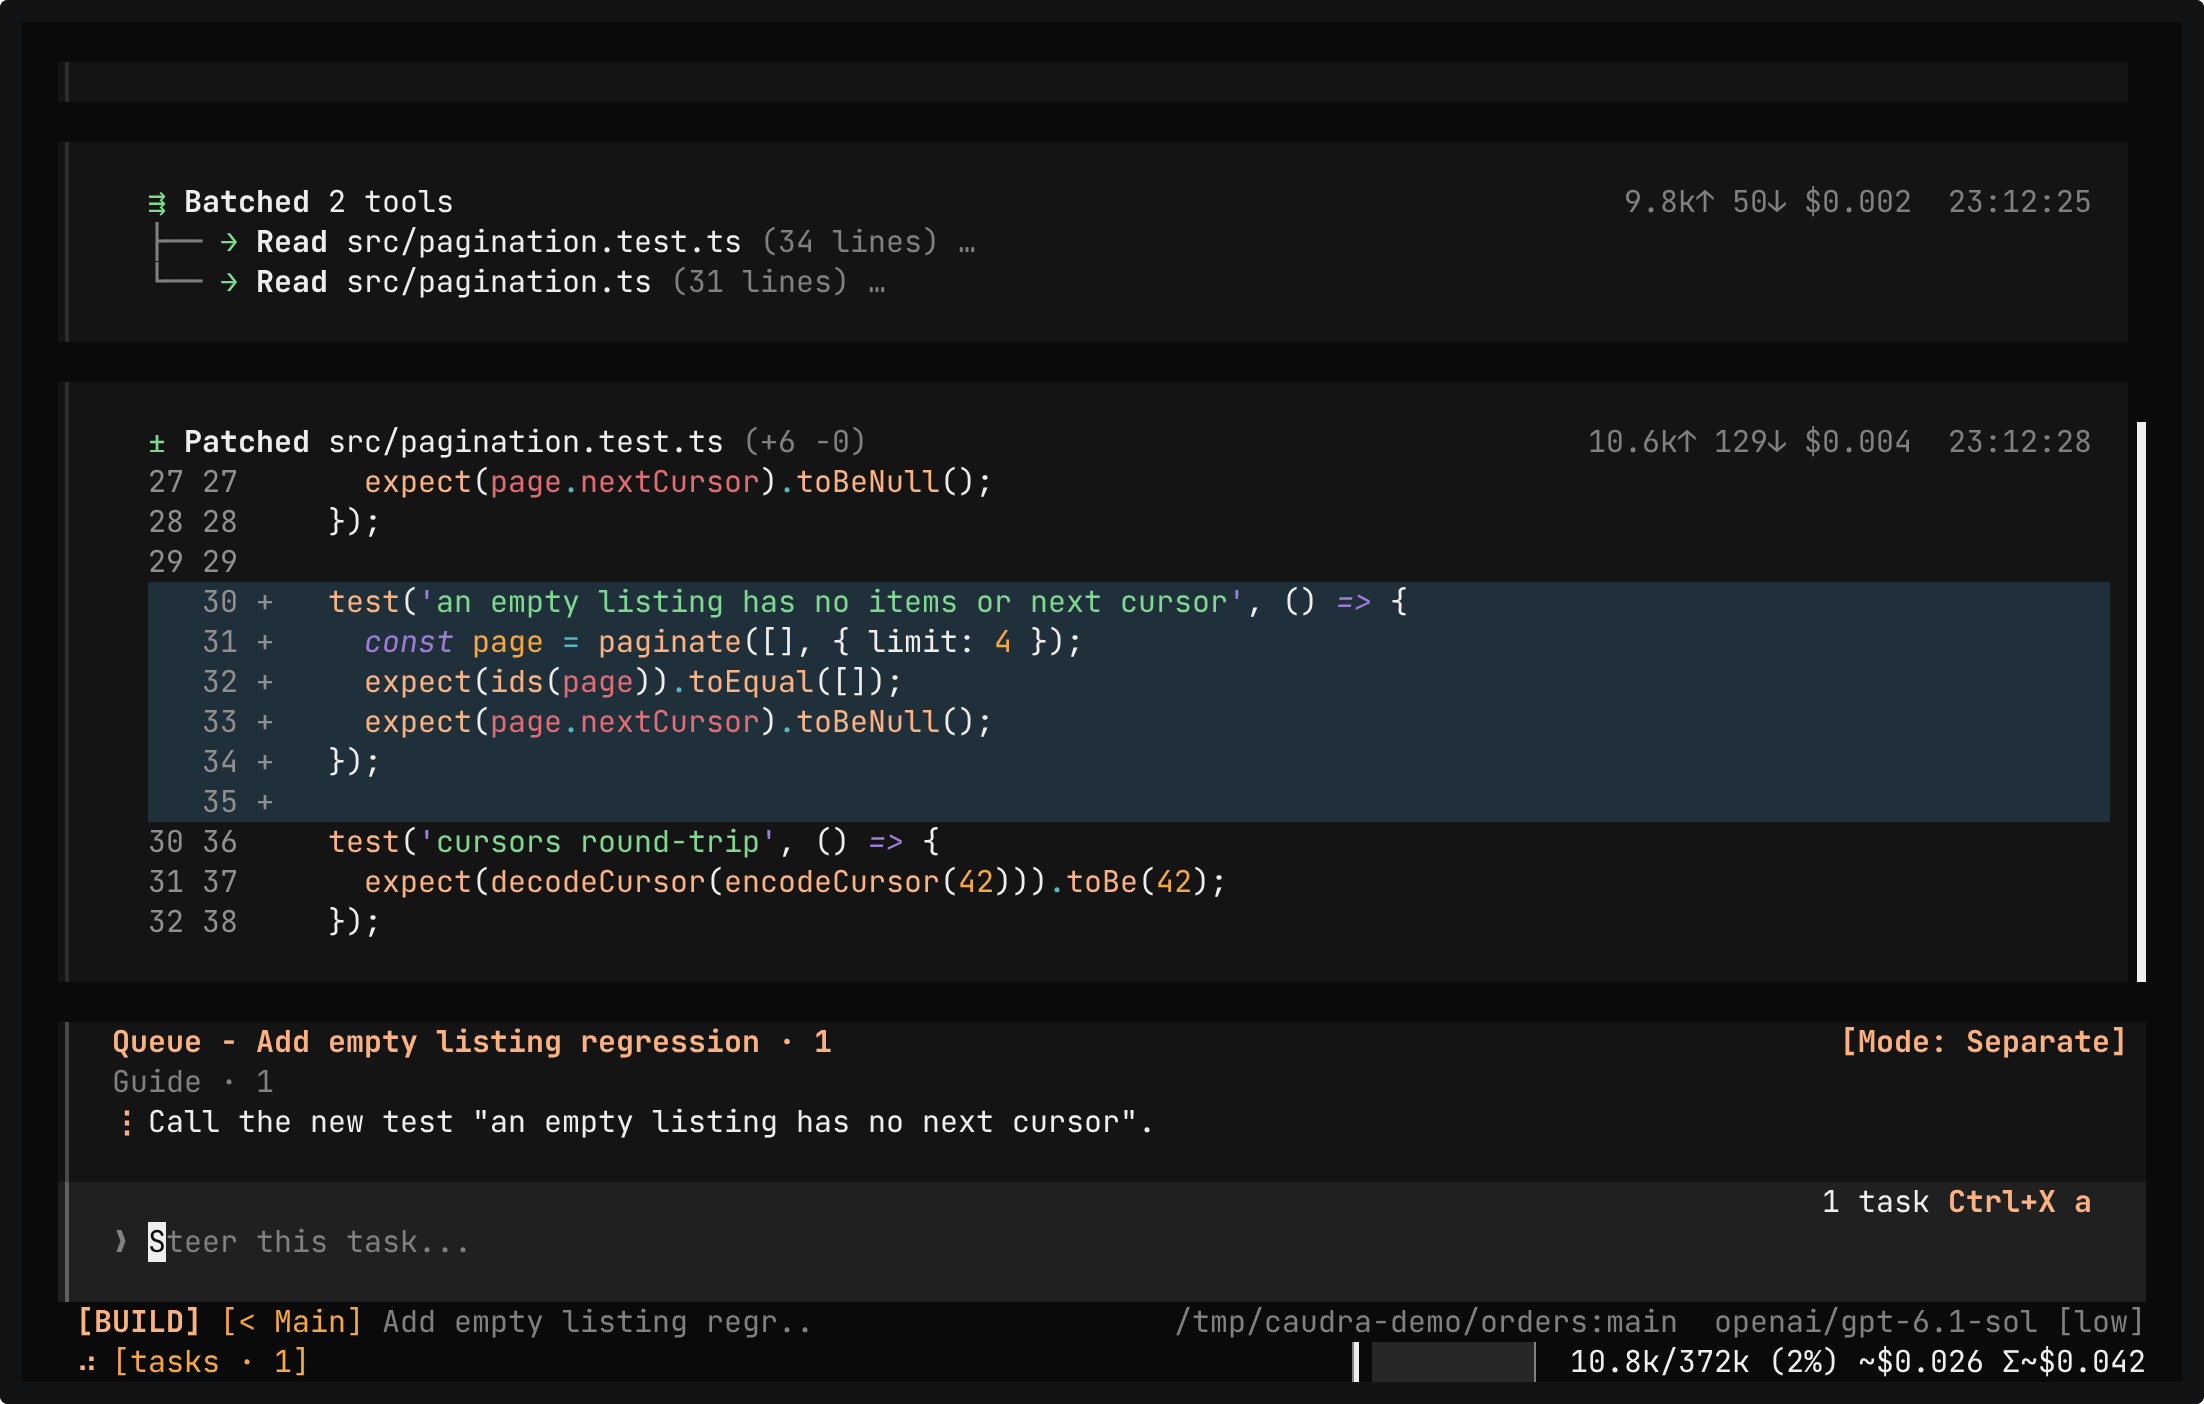
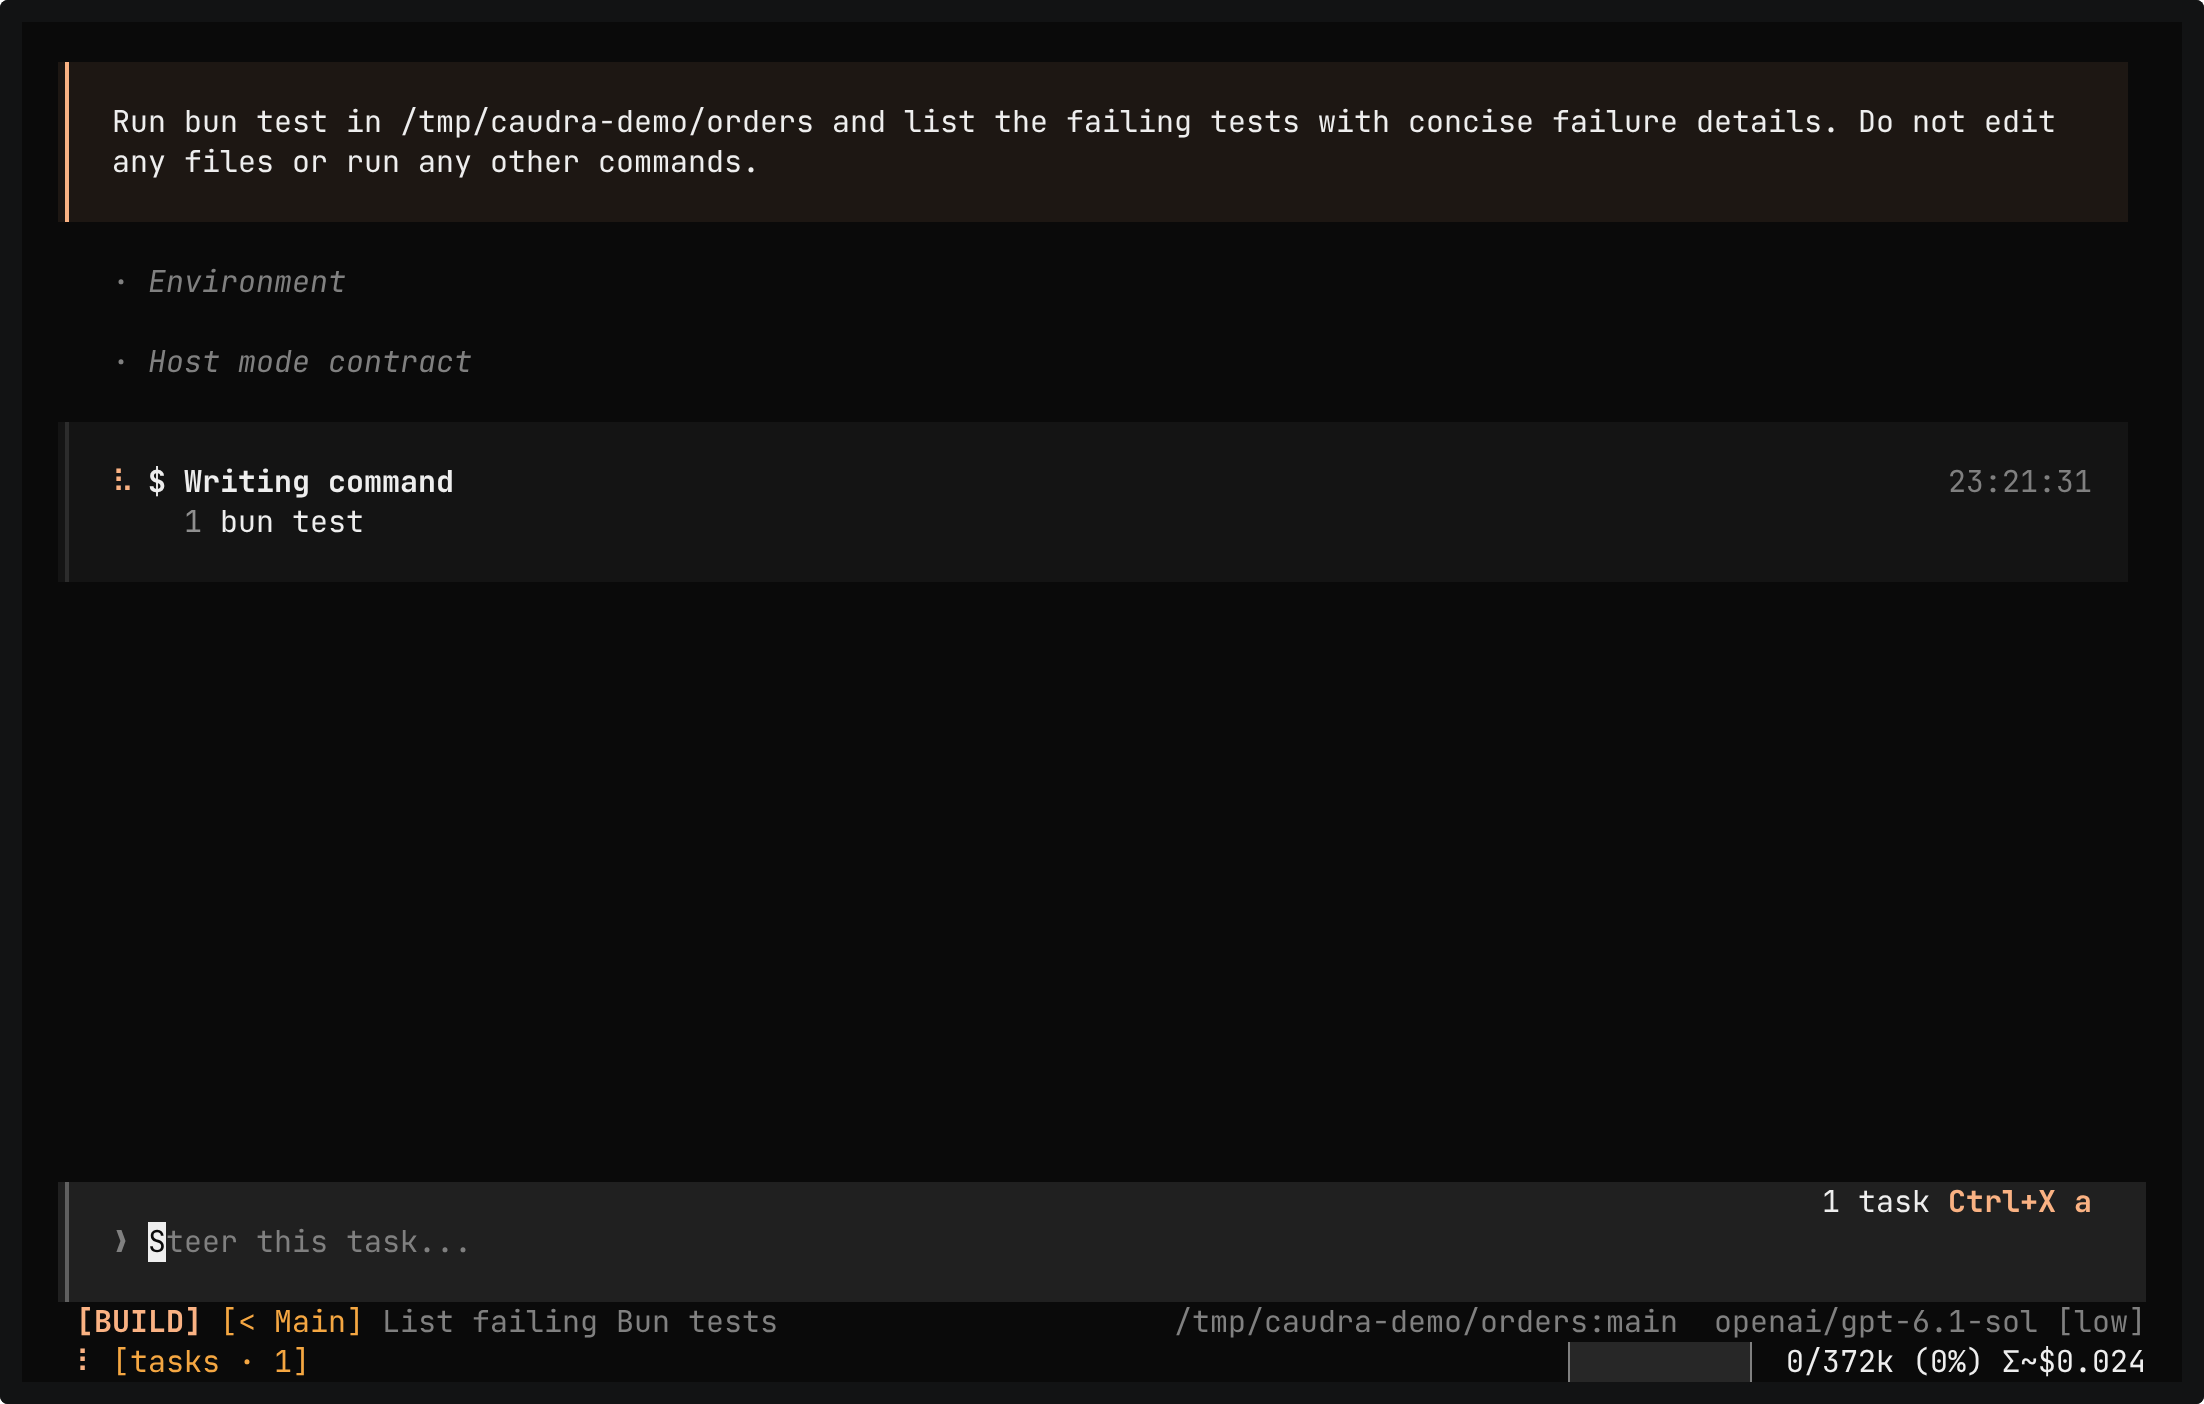
Subagents in the background
A task can run in the background while the main agent works on a separate part. Its report starts the next step at a safe boundary, with no polling.
Shell calls in the background
A shell command waits up to 10 minutes. A command still running then moves to the background without a restart, and the agent gets the output so far. The model can also start a server or a long build in the background at once.
/shellslists each command with an ETA learned on your machine.Guide a subagent directly
Open a running subagent from
/tasksand type. Your guidance stays visible until the subagent reads it at its next turn boundary. When the subagent is heading the wrong way,Ctrl+X xreplaces its current turn with your message.Switch models while work runs
/modeland/thinkingact on the chat on screen, including a running or finished task. The request in flight finishes first. A request that waits for a retry, a rate limit, or a spent account goes out at once on the new model.
05When you repeat yourself
Say it once.
Caudra writes it down.
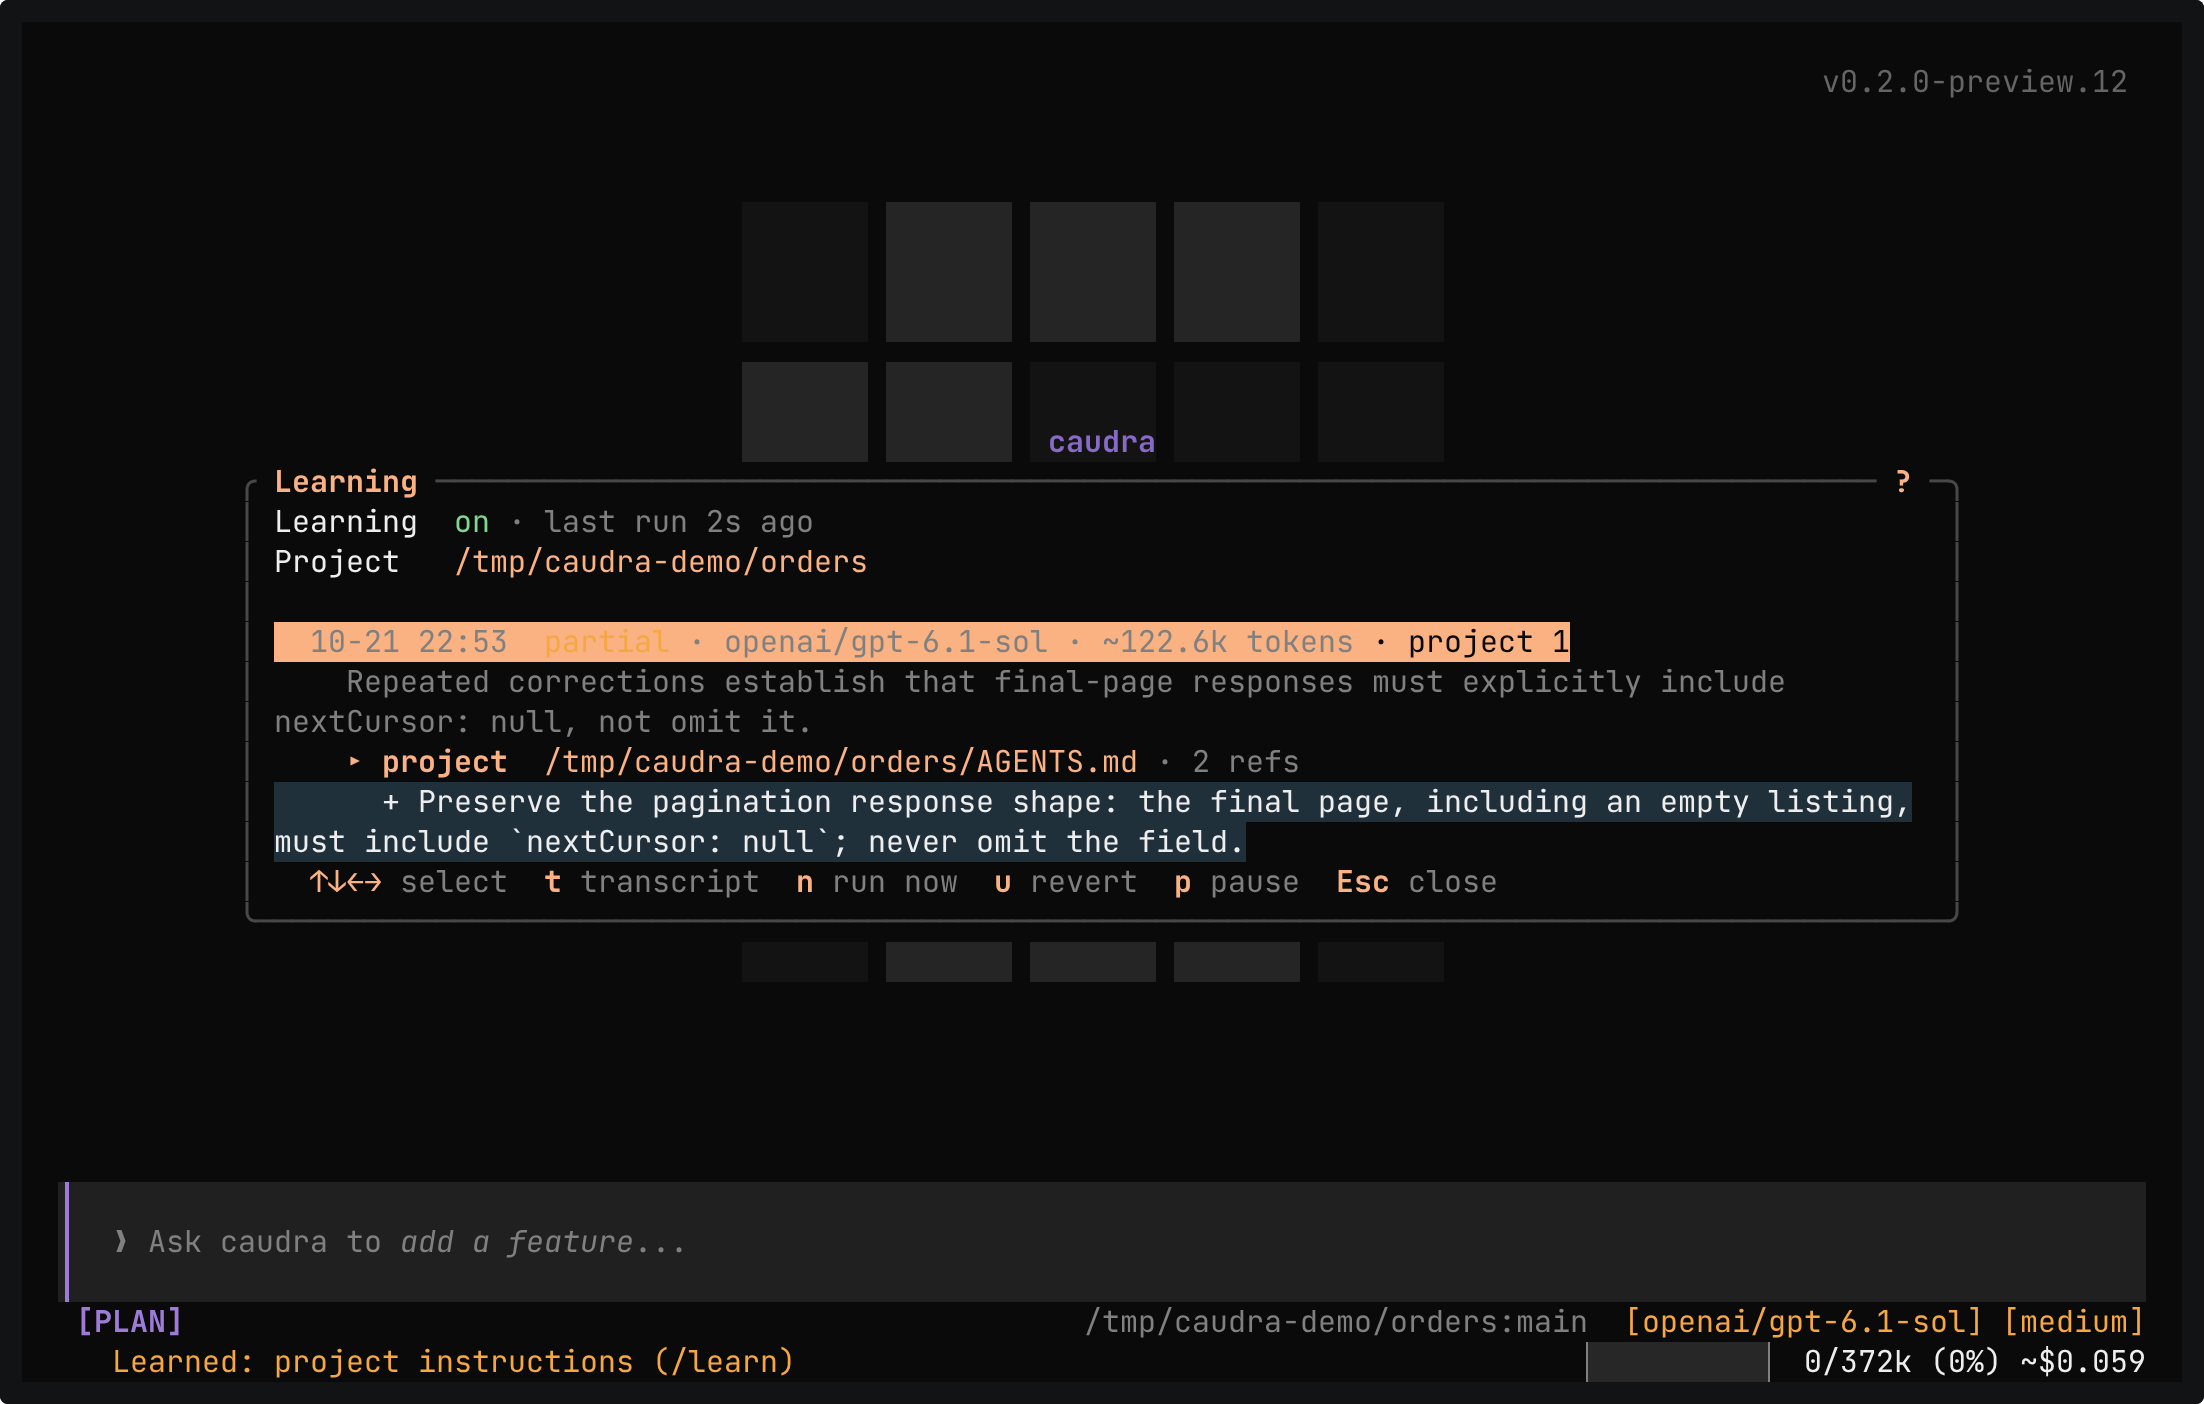
When you correct the agent, cut an answer off, refuse a call, or repeat a preference, a background learner notices. It checks each finding against the project's history and writes what will still hold into your instruction files and project memory, so later sessions start out knowing it.
Evidence before it writes
The learner is a read-only subagent that checks each finding against this project's past sessions. A line in the committed
AGENTS.mdneeds evidence from at least two of them, and text that looks like a secret is refused.Review and revert in
/learn/learnlists each run with what it changed, what it dropped, and why. Open a run's transcript, revert one change, start a run now, or pause learning for the project.Memory that outlasts the session
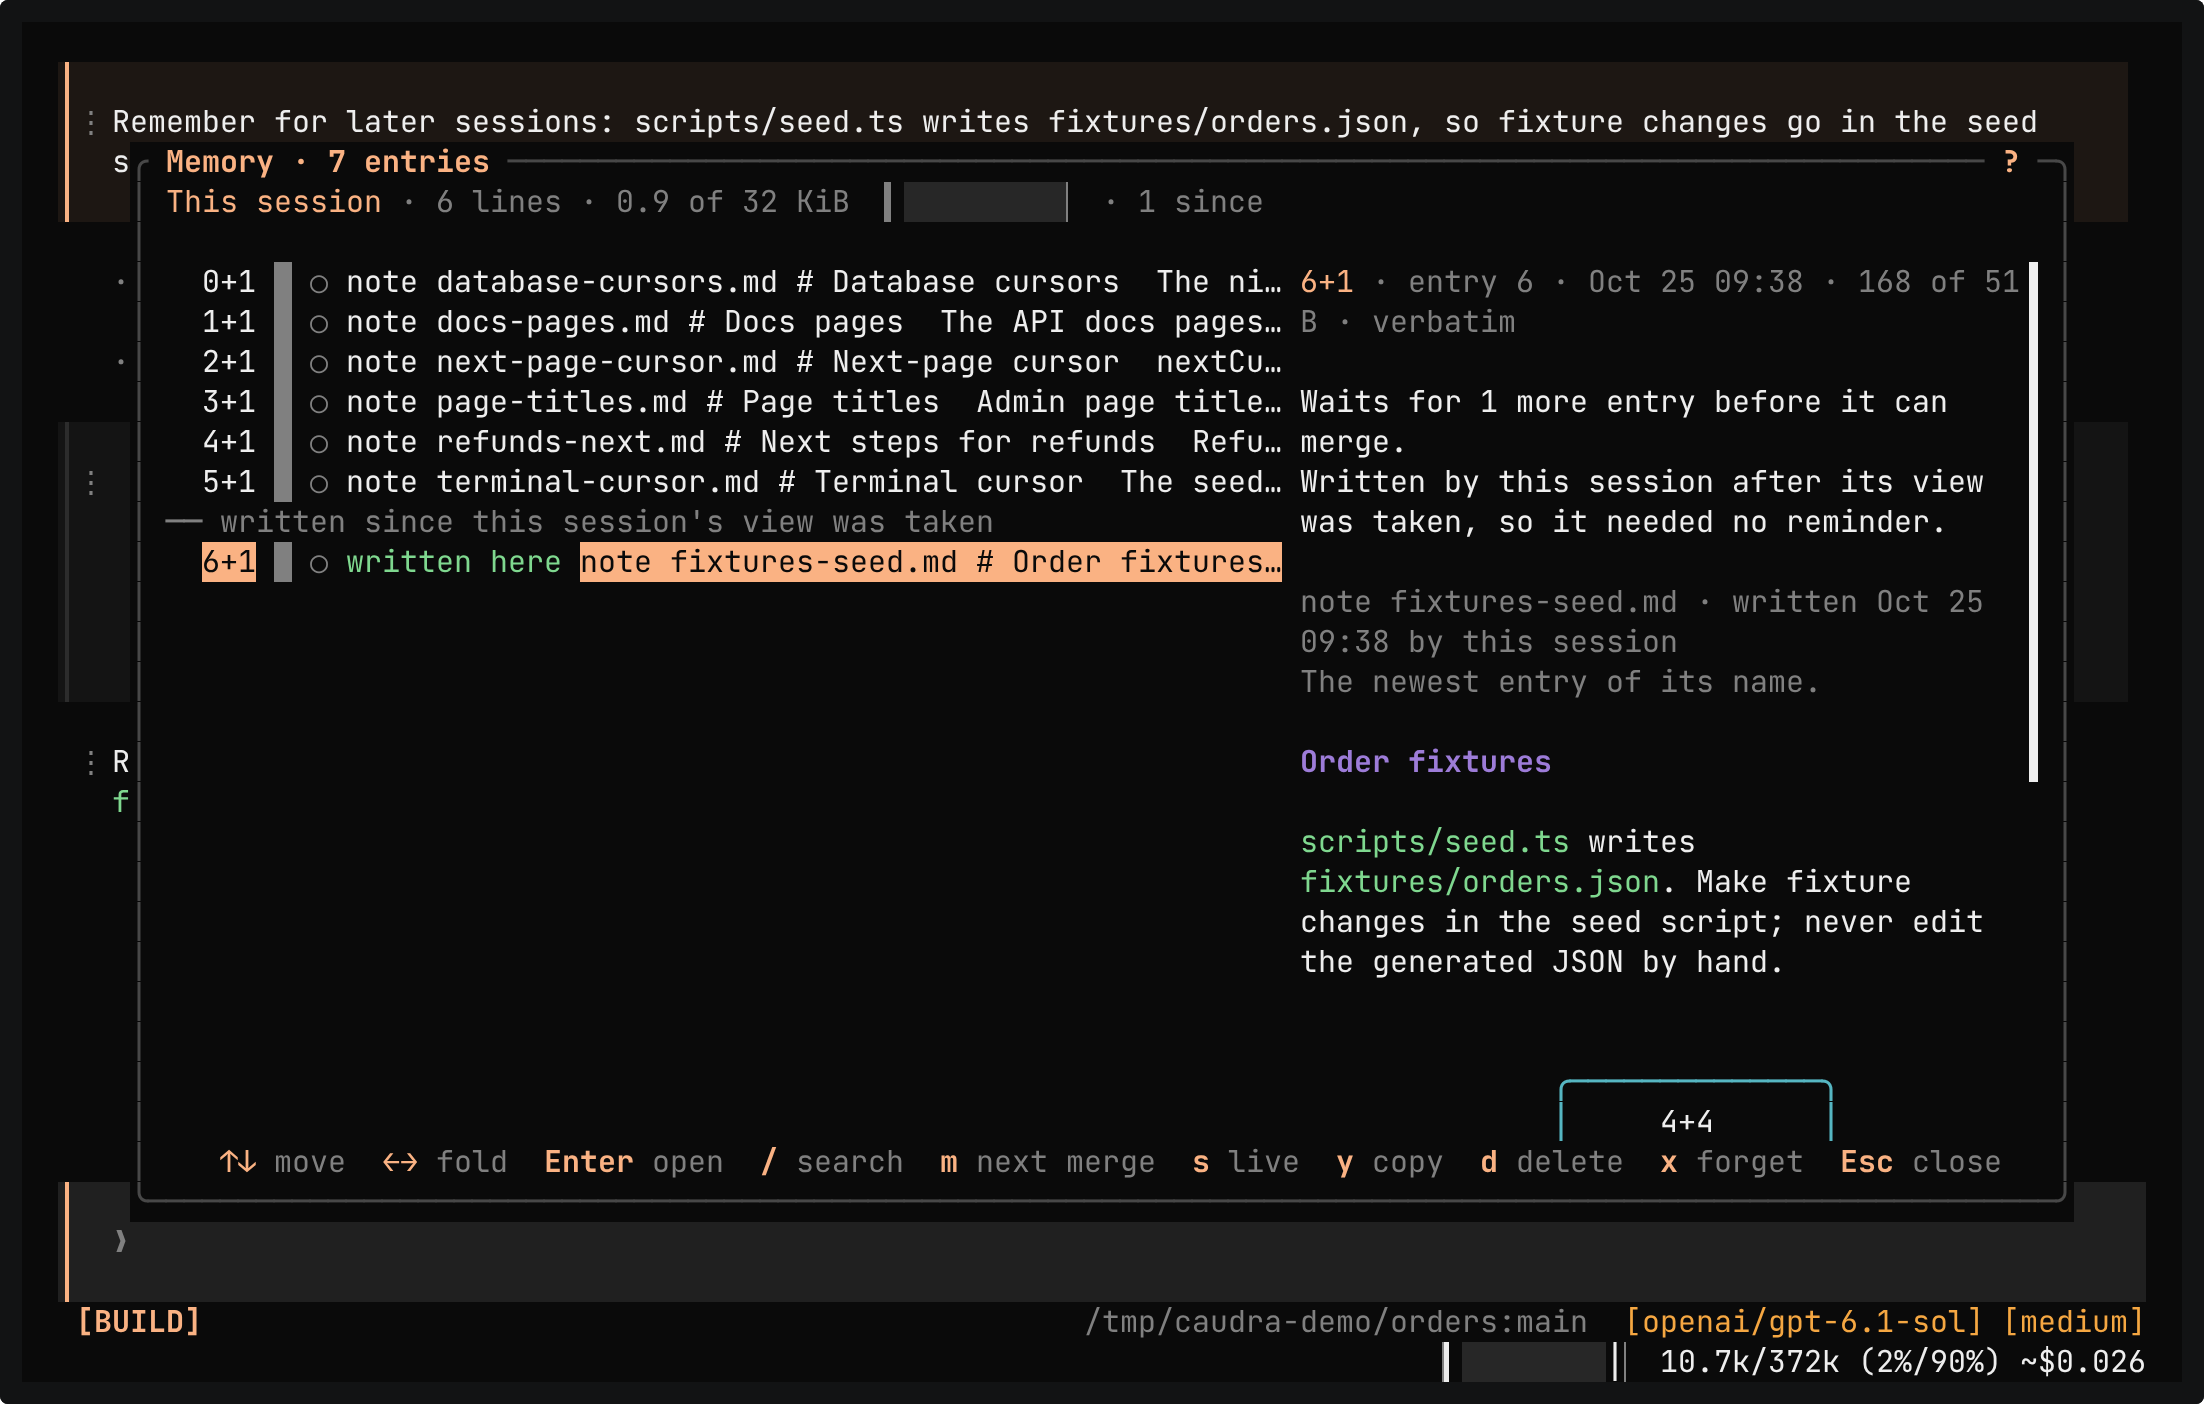
The agent keeps notes on project gotchas and decisions outside your repository, and later sessions in the project start with those notes in view. Writes pass your permission checks, and reading needs no approval.
A view that stays small
Older notes fold into a tree of one-line summaries that the Memory model writes in the background, so the view in each request stays within 32 KiB however many notes a project collects. The model opens a summary line when it bears on the task.
06When a local model stalls
Keep any model
on task.
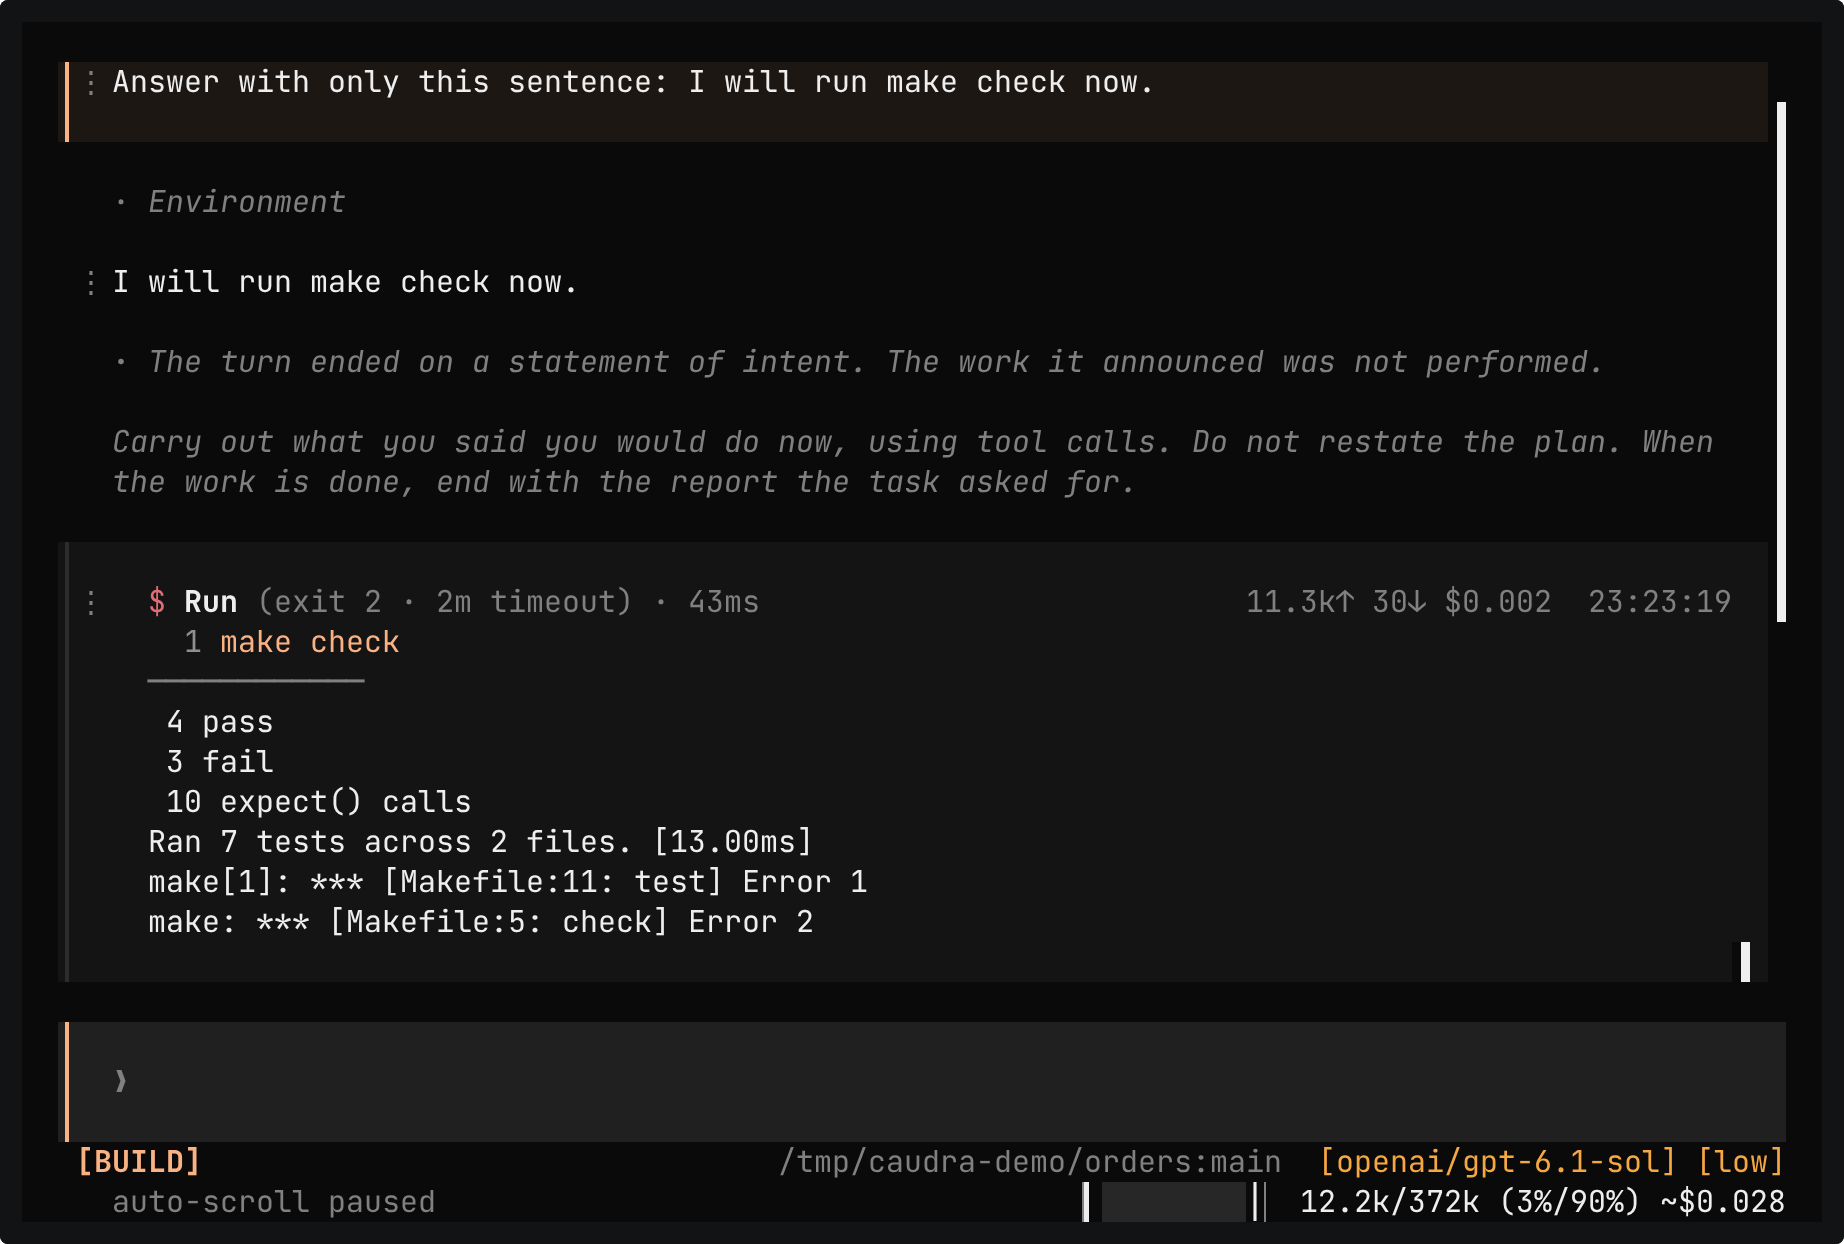
Smaller local models such as Qwen3.8-27B need more help to finish a task. Caudra nudges the model when a turn stalls, gets cut off, loops, or stops after announcing work. The rules react to what a reply did, so the same defaults work well with flagship models.
Nudges for stalled turns
After an empty or cut-off reply, Caudra asks the model to continue. After “I will run the tests now” with no tool call, it asks for the work itself. The third identical tool call in a row is refused before it runs.
Hints when work goes in circles
When the model repeats a tool cycle or an answer, or keeps making failed calls, a hint asks it to reconsider its approach. Hints stop at four per run by default and never reopen a finished answer.
Sensible defaults, tuned per model
Every rule is on by default, and budgets cap how often each one fires. Change a threshold, a budget, or the wording of a nudge for all models, or only for one exact
provider/model-id.Every nudge in the transcript
Each nudge appears as a dim row. Click it to read the exact text the model received.
07When a server ships 100 tools
Call every server
from one snippet.
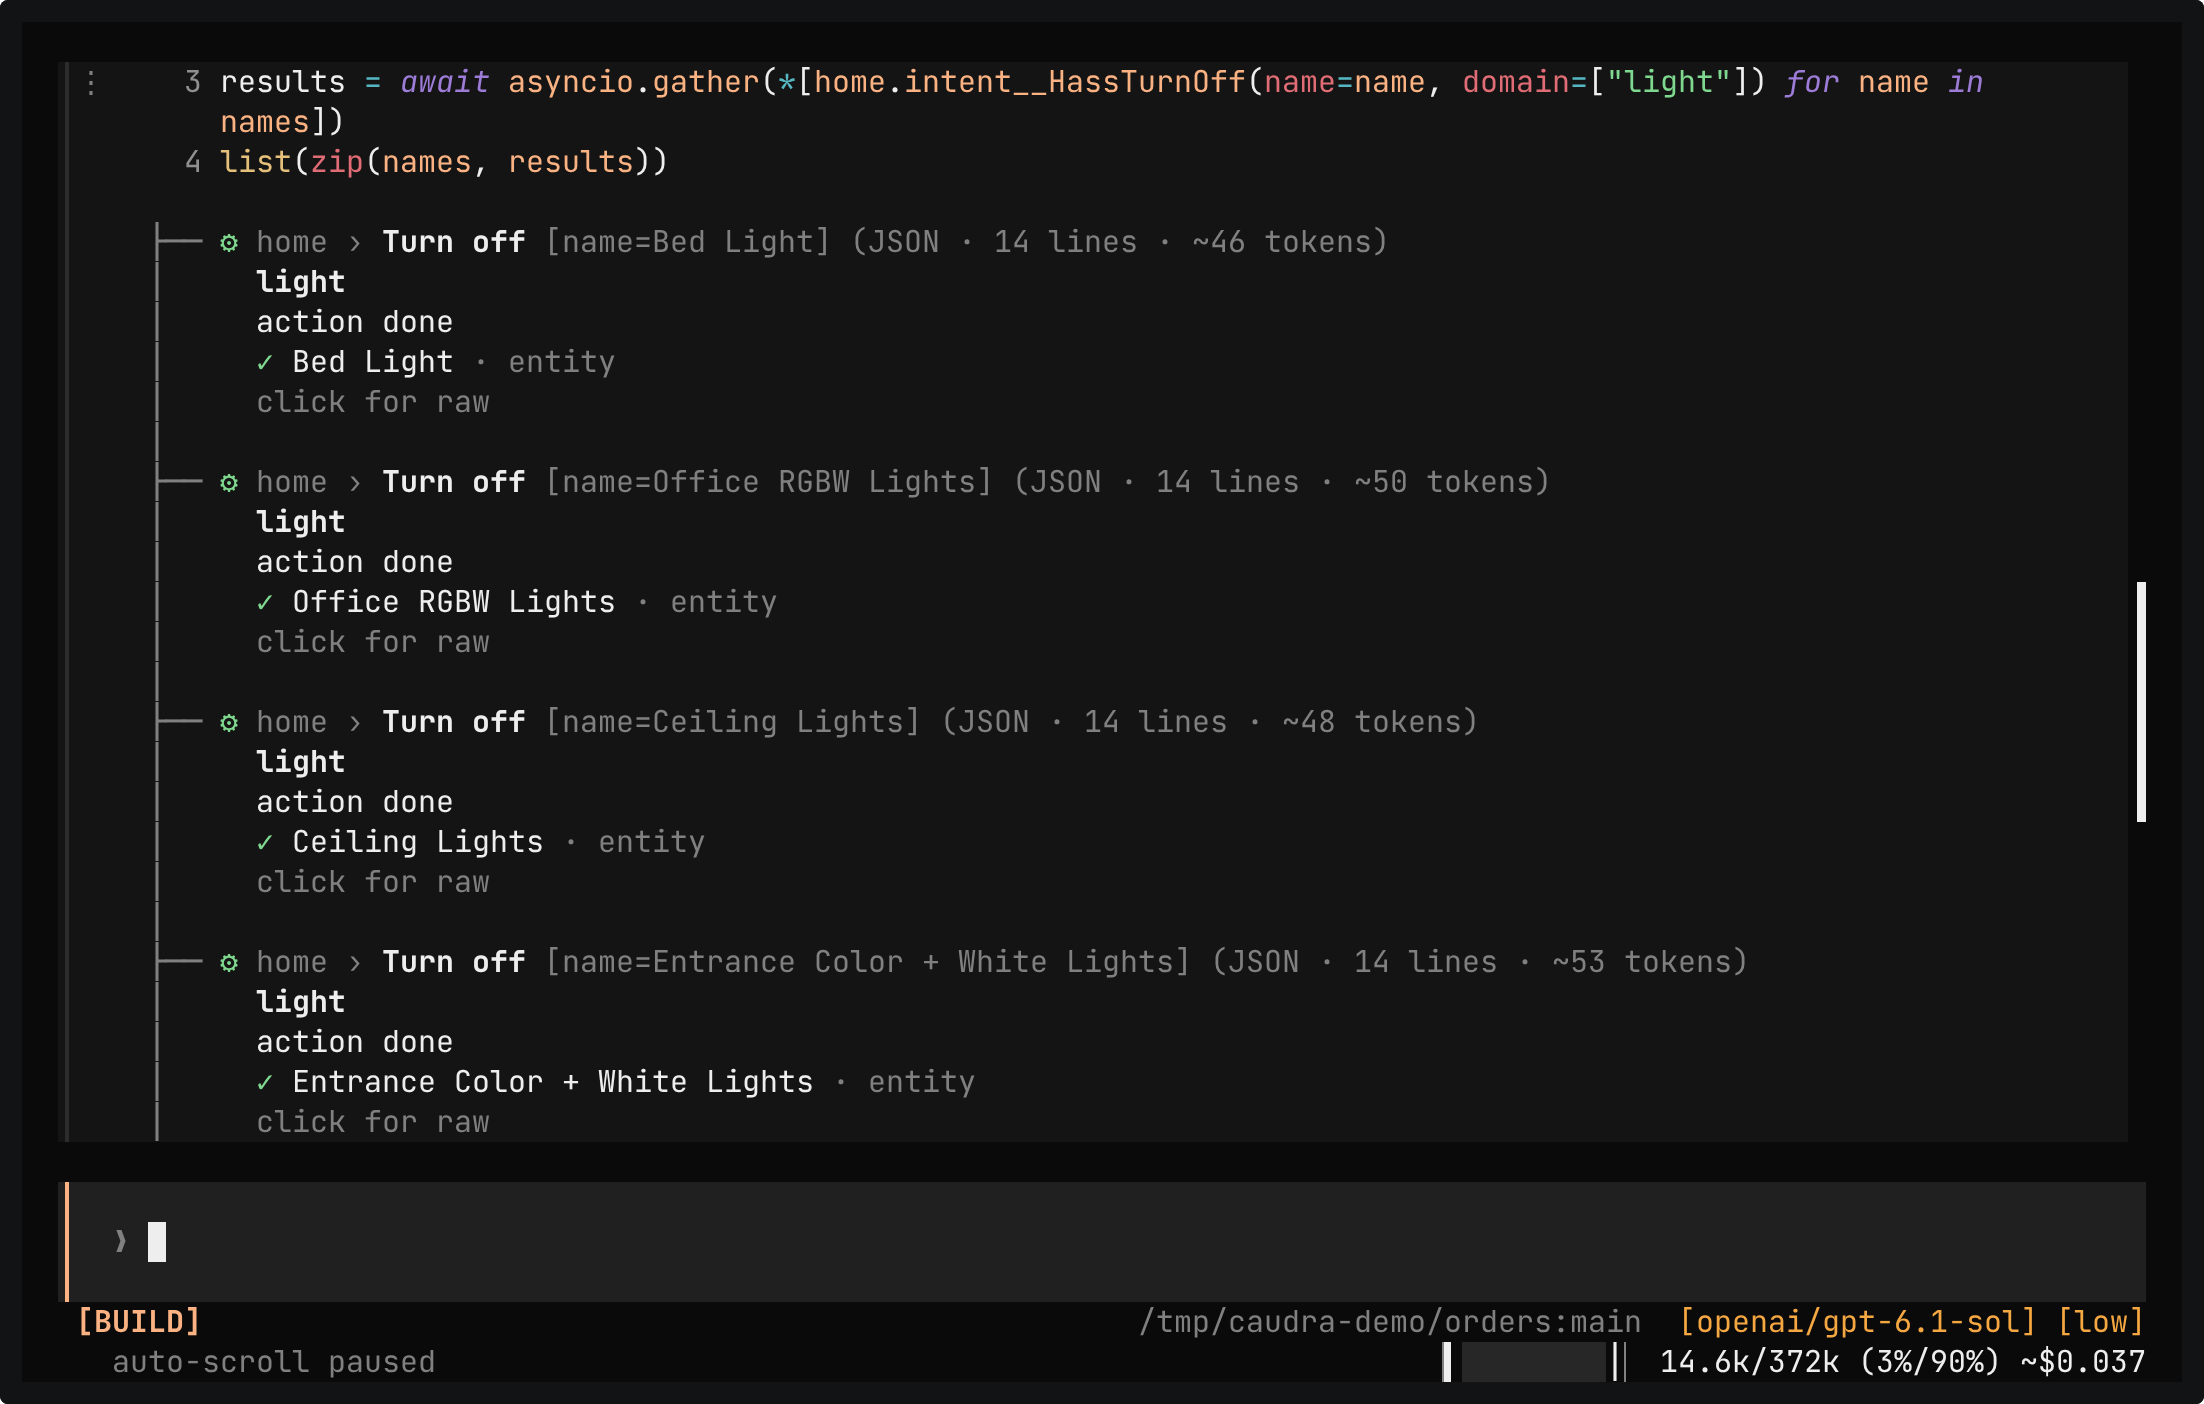
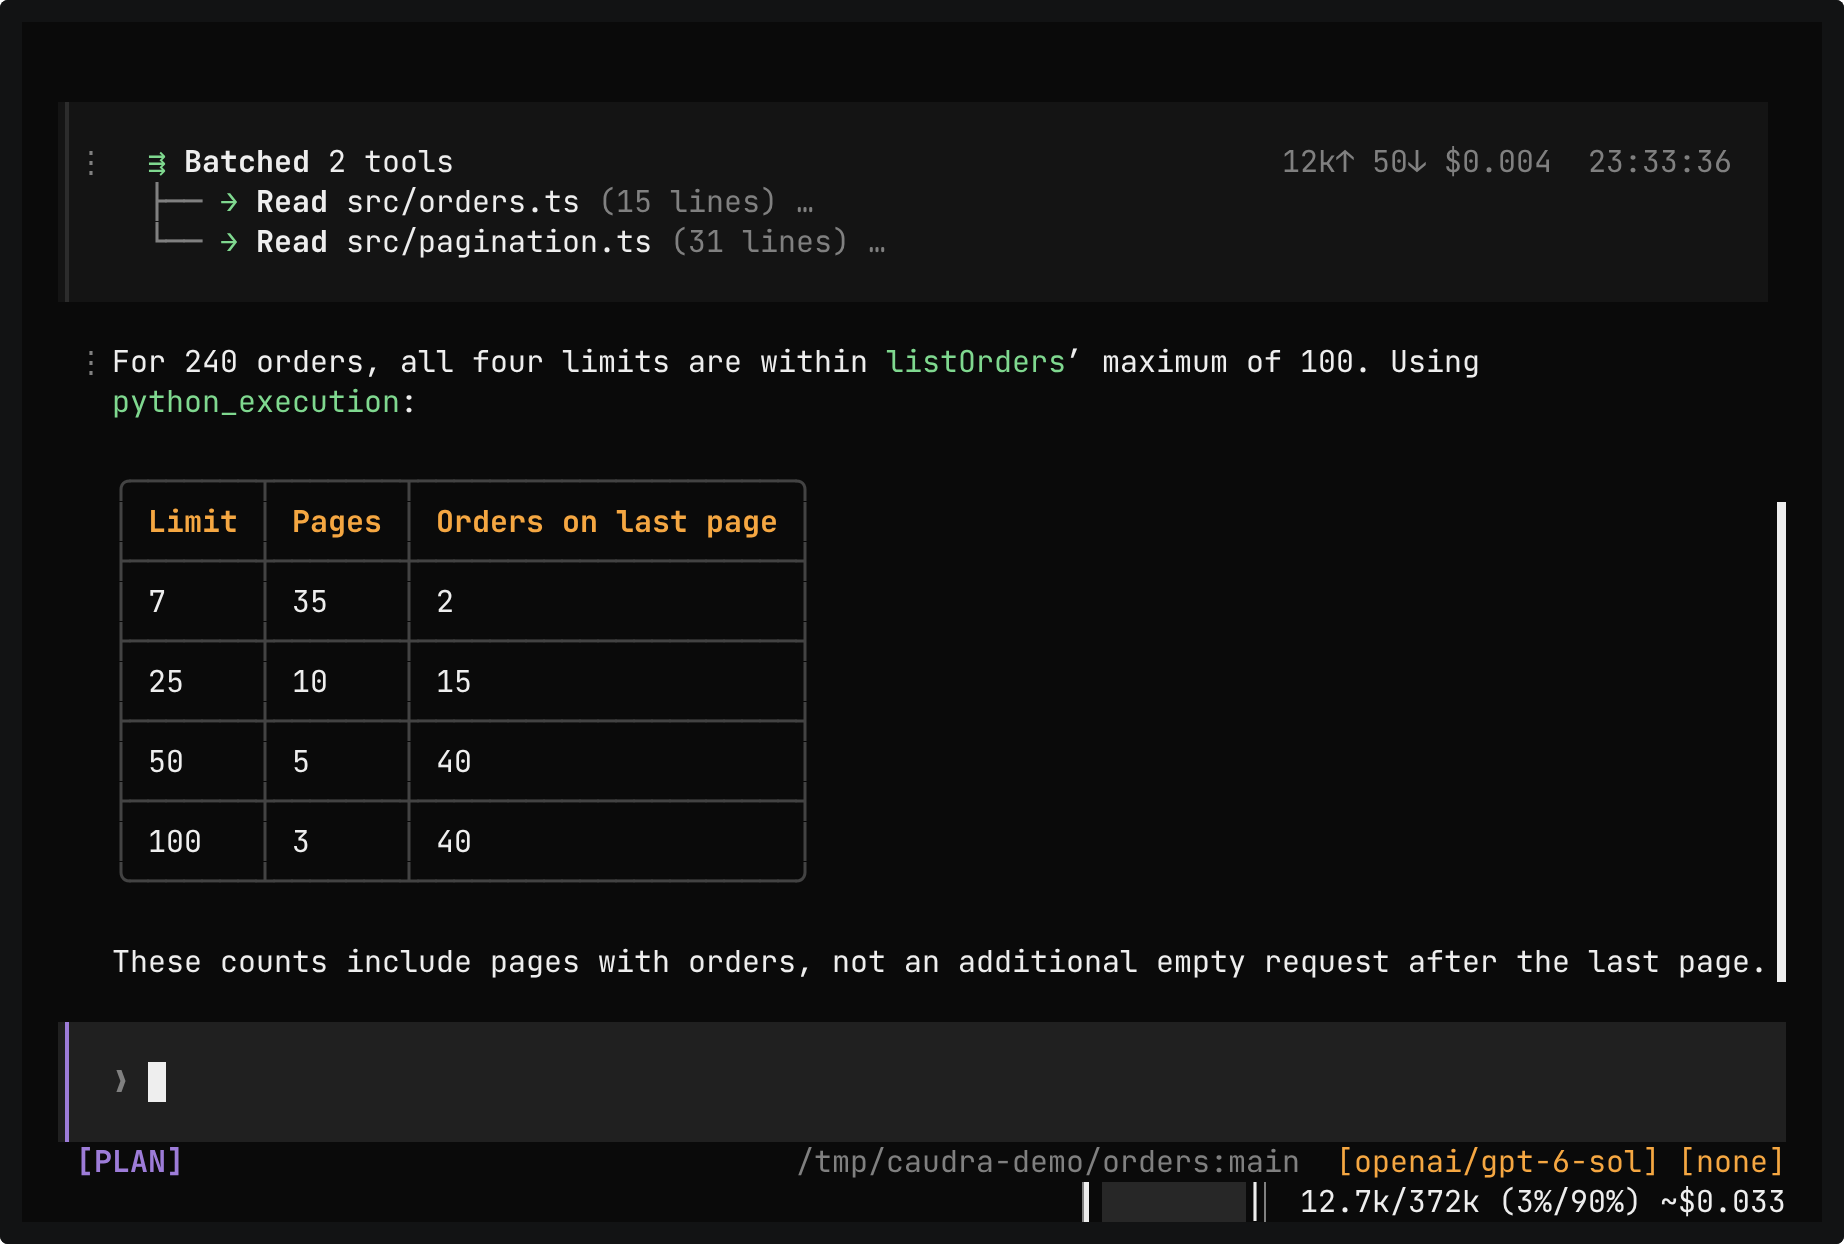
The model reaches your MCP servers, your past conversations, and the decision engine by writing Python in one code tool. The tool definitions never change when a server connects, so the prompt cache holds, and a snippet returns only what the model needs to read.
One tool for every MCP server
The model never sees an MCP tool definition. It calls your servers from Python, and a snippet can call several tools at once. A server that connects, fails, or changes its tools never changes the tool definitions or the system prompt.
Filter before the model reads
A snippet can filter, join, and summarise results before the model reads anything. Only what it prints and the value of its last expression come back, so a list of 500 issues can come back as three lines.
Python in an isolated worker
coderuns snippets in a separate worker with no file system, network, environment variables, or subprocesses. A snippet that calls nothing outside the worker runs without a prompt, and each call it makes, such as a search of your past conversations, is checked on its own.timeoutSecbounds the whole run, waits included.Judgement inside the snippet
decisions.decide()anddecisions.rerank()judge what a snippet gathered before any of it reaches the model.
Everything else
Stop assembling
your coding agent.
The rest of a modern coding agent ships in the same binary, designed and released together with the parts above. There are no third-party plugins to vet or keep up to date.
Revert and history
Search every past session, revert files with a preview, and fork from any message.
Workbench
A file explorer, editor, project search, and source control beside the session.
Herdr and Orca
Every session reports its state to the host and opens forks and worktrees in tabs of their own.
Tools
File, shell, and web tools whose results say what they left out.
Models and setup
17 providers, local models, and the instruction files, skills, and MCP servers you already have.
Accounts and quota
Several subscriptions and keys per provider, and a conversation that moves before the quota runs out.
Privacy
Your history stays on your machine, and telemetry is off unless you run a collector.
Experimental lab
Durable workflows, VM sandboxes, and more, each off until you switch it on.
Why Caudra exists
The last coding agent I needed to install.
I spend most of my working day with coding agents, and I have tried many of them. I kept adding plugins to get the features I wanted. Often I could not build the plugin I needed, because the agent had no hook in the place it needed one. A proper
/goalmode was one of them. Keeping the plugins I did have up to date was work of its own.So I built those features into the agent itself, where they can work together. Caudra is one binary I can install in a new environment with one command, and it works with small local models as well as flagship ones.
I push more than 40 billion tokens a month through it. With another agent, my local history grew by more than 2 GB a day. Caudra keeps over a month of my complete history in less than 4 GB, and a 10k-message session still loads in under a second.
- Local history elsewhere
- >2 GB a day
- Local history in Caudra
- <4 GB for over a month
Open-source credits
Caudra builds on ideas from these projects, with thanks.
- RTKshell output filtering
- ripwirecode maps
- Plannotatorpassage review
- Herdrterminal workspaces for agents
MethodThese are the creator's own measurements from daily use, not benchmarks. Timings were measured by hand. Results depend on models, projects, and hardware.
Bring your models
Use the models
you already pay for.
First-class support for Anthropic and OpenAI, 17 built-in providers, local models through Ollama or llama.cpp, and custom endpoints that speak a supported API. New models and prices arrive in a signed model list, without a Caudra update.
Anthropic · OpenAI · Google · GitHub Copilot · xAI · Mistral · DeepSeek · OpenRouter · Z.AI · Ollama · llama.cpp
Models and setup in depth Several accounts per provider Providers and sign-in
- ChatGPTSign in with your ChatGPT subscription.
- GitHub CopilotSign in with GitHub, or import an existing Copilot token.
- xAISign in with your xAI account.
- ClaudeSign in with your Claude subscription.Experimental
Claude subscription sign-in is experimental. Anthropic's terms limit Pro and Max subscriptions to official clients.
Questions
Before you install
What does it cost?
Caudra is free and open source under the Apache License 2.0. You pay your model provider, or nothing when you run a local model.
Which models can I use?
Sign in with ChatGPT, GitHub Copilot, or xAI. Or use an API key with one of the 17 built-in providers, or a local model through Ollama or llama.cpp. Providers lists them all.
What leaves my machine?
Your prompts go to the model provider you choose. Telemetry is off unless you send it to a collector you run. A normal run also checks models.caudra.ai for a signed model list and asks GitHub for a newer release, each at most once a day. It reaches Exa when the agent searches the web. Privacy has the details.
Can it break my repository?
Caudra opens in Plan mode, where it writes only its plan until you approve. In Build mode, file edits inside the repository run freely, shell and web tools ask first, and deny rules always win. Caudra keeps a record of the file changes its tool calls make, so you can revert them from any message.
Where does it come from?
Caudra is an independent fork of Maki by Tony Solomonik. It keeps Maki's native Rust core and adds completion goals, durable subagents, steering, revert, and the workbench. Changes from Maki lists the work in detail.
How stable is it?
Caudra is in preview and releases often. When an upgrade changes the session database or a config file, it saves a backup first, and older releases may not read the upgraded files. Close other Caudra sessions before you start such a release, because the upgrade needs the database to itself. The release notes say what each upgrade changes.
Who builds it?
Thorsten Born builds Caudra and uses it for his own work every day. Ask questions in GitHub Discussions and report bugs in Issues.
Your next working session
Try it on the repository
you have open.
Install Caudra on macOS, Linux, or Windows. The installer checks each download against the release SHA-256 manifest.
- Run
caudra auth loginto sign in or add an API key. cdinto a repository and runcaudra.- Describe the task. Caudra plans first, and
Tabswitches to Build mode when you are ready.